EDF9850_Example5a_Part1
 Watch on YouTube →
Overview
Lesa Hoffman reviews multilevel and longitudinal modeling, showing how within-person, between-person, and contextual effects connect to random slopes, missing-data decisions, and repeated-measures ANOVA. Using simulated data based on a 207-person, 21-day diabetes study, she demonstrates R’s nlme::lme, person-mean centering, and AR(1) residual correlation to model daily glucose and negative mood; neither study day nor day of week shows a systematic glucose effect.
Key takeaways
- For a constant-centered Level 1 predictor, the Level 2 coefficient is contextual and the between-person effect equals within plus contextual; with cluster-mean centering, the Level 2 coefficient is between-person and contextual equals between minus within.
- A random time slope represents person-to-person differences in change rates, and time-invariant predictors can explain those differences through cross-level interactions.
- In the longitudinal models discussed, missing a time-varying value drops an occasion, but missing a time-invariant predictor can remove every occasion for that person; imputation or multilevel SEM with FIML are alternatives.
- A random intercept imposes constant within-person correlation across occasions, whereas an AR(1) residual structure allows correlation to decay with time separation; nlme::lme can fit both together.
- Traditional repeated-measures ANOVA can discard all observations from participants missing any occasion; likelihood-based mixed models retain incomplete longitudinal records and can incorporate time-varying predictors.
- In Hoffman’s 207-person, 21-day simulated diabetes example, negative mood–glucose correlations are modest, and tests find no systematic glucose effect of study day or day of week.
Chapters
0:00
Week Nine Deadlines, Project Guidance, and Course Logistics
- Homework 3 is due Wednesday during Hoffman’s conference travel; Monday office hours remain available, but Tuesday office hours are canceled.
- The five planned activities are complete, and the next major deadline is project check-ins before presentations.
- Project teams do not need to conduct a power analysis; limited sample size should instead be reported as a study limitation.
5:30
Activity 5: Recovering Between and Contextual Effects
- With a constant-centered Level 1 predictor, the Level 2 coefficient is contextual; add the within-person effect to recover the between-person effect.
- With a cluster-mean-centered Level 1 predictor, the Level 2 coefficient is between-cluster; subtract the within effect to obtain the contextual effect.
- A random slope requires the cluster-mean-centered predictor, because the contextual-effect setup does not estimate the intended random slope.
12:30
Longitudinal Levels, Time-Varying Predictors, and Missingness
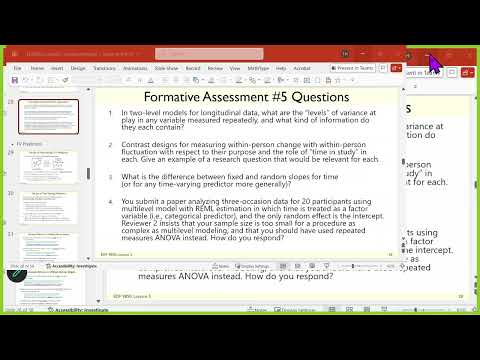
- In a standard repeated-measures design, occasions are Level 1 and people are Level 2; intensive daily studies can add a third level for days within people.
- Within-person, intraindividual, and time-varying describe Level 1; between-person, interindividual, and time-invariant describe Level 2.
- Under the models discussed, missing time-varying data removes the incomplete occasion, while a missing time-invariant predictor removes that person’s rows from the analysis.
- Multiple imputation or multilevel structural equation modeling with full-information maximum likelihood can address missing predictors beyond the basic framework.
21:00
Random Time Slopes and the Difference Between Change and Fluctuation
- A fixed time slope assumes a common trajectory; a random time slope allows the rate of change to vary across people.
- Time-invariant predictors can explain why people start at different levels or change at different rates through cross-level interactions.
- Growth studies deliberately choose the number and spacing of occasions to capture a change process; fluctuation studies use repeated measurements to observe momentary variation.
- Examples include piecewise modeling of cortisol’s morning rise and decline, and an apparent stress decline caused by participants learning to shorten daily phone interviews.
29:30
Why a Random-Intercept Model Can Be Better Than Repeated-Measures ANOVA
- A wait-list intervention with three occasions and a random intercept can represent the same compound-symmetry covariance structure as a repeated-measures ANOVA.
- Traditional ANOVA uses least squares and typically discards participants missing any occasion; in Hoffman’s dissertation example, that would remove about half the sample.
- Likelihood-based mixed models can retain available repeated observations and accommodate time-varying predictors, which standard ANOVA handles poorly.
- The alternative MANOVA or unstructured covariance model estimates separate occasion variances and pairwise covariances, but becomes impractical with many occasions.
38:00
Example 5A: Simulated Diabetes Data and Person-Mean Centering
- Hoffman analyzes simulated data modeled on a type 2 diabetes study with 207 people measured over 21 days.
- The outcome is next-morning glucose, log-transformed because of skew; higher values indicate worse glucose outcomes.
- Negative mood is the main daily predictor, and person-mean centering separates each day’s mood deviation from the person’s average mood.
- The raw, within-person, and between-person mood–glucose correlations are approximately .14, .12, and .18, respectively.
43:30
Interpreting Empty Models and Person-Level Variability
- Hoffman uses nlme’s lme function, whose syntax separates fixed and random effects and specifies REML with method = "REML".
- The negative-mood empty model has an intraclass correlation of .386, meaning roughly 38.6% of variation reflects average differences between people.
- The glucose empty model indicates that about 75% of its variability is stable across days within people.
- A random-intercept model assumes constant correlation across all occasions for a person, regardless of how far apart the days are.
48:30
Adding AR(1) Residual Correlation with nlme
- Daily observations closer together may be more correlated than observations weeks apart, so Hoffman adds a first-order autoregressive structure to Level 1 residuals.
- In nlme, correlation = corAR1(form = ~ study_day) encodes the spacing between occasions, including when observations are missing.
- An AR(1) parameter near .48 means residual correlation decays by powers of .48 with each additional day of separation.
- Likelihood-ratio model comparisons support retaining both the random intercept and AR(1) residual correlation; the test for AR(1) is about 900.
55:30
Reading the Implied Covariance Pattern and Its Consequences
- The combined model keeps variance constant across days while allowing covariance—and therefore correlation—to decline as occasions become more distant.
- The random intercept supplies a persistent correlation floor, while AR(1) adds stronger residual dependence between nearby days; the long-lag correlation approaches about .722 in this example.
- Modeling residual dependence matters even when autocorrelation is not a research question, because misspecification can inflate Type I error rates and distort standard errors.
- Hoffman notes that ordinary lmer does not offer this residual-correlation option, motivating use of nlme for the example.
58:15
Testing Whether Glucose Changes Across the 21 Study Days
- Treating study day as a factor adds 20 fixed-effect contrasts, each comparing one of days 2–21 with day 1.
- A joint test of all 20 coefficients finds no overall study-day effect on glucose, and the predicted-means plot shows no systematic trajectory.
- The estimated day-7 and day-14 deviations are positive, but the broader test does not support a consistent time trend.
1:01:15
Day-of-Week Effects and Classifying the Study as Fluctuation
- Hoffman also tests day of week, adding six contrasts with Saturday as the reference; the joint test finds no overall weekday effect.
- Pairwise weekday comparisons are not significant after Tukey adjustment for multiple tests.
- The absence of study-day and weekday effects supports treating the 21-day glucose example as a fluctuation study rather than a systematic change study.
- At 62:33, Hoffman pauses for a planned five-to-six-minute break before continuing with three more models.
Summary, takeaways, and chapters were generated by AI from the video's transcript and may contain errors. The video belongs to its creator, Lesa Hoffman.