Math 1153 - 5 November 2026 - Section 13.3, Chapter 14
Overview
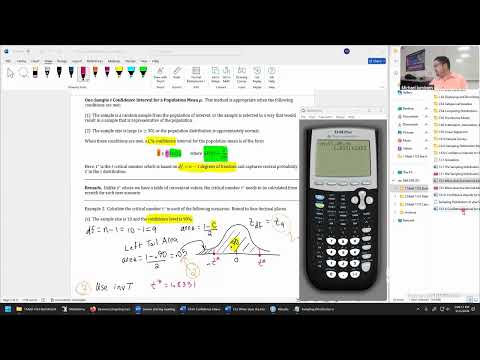
Mike Jacobsen closes Chapter 13 by reviewing how sample size and confidence level affect confidence intervals, then introduces Chapter 14’s interval for a population mean. He explains the central limit theorem, replaces the unknown population standard deviation with the sample standard deviation, and shows why that added uncertainty requires the t distribution, including a 90% example with 9 degrees of freedom and t* = 1.8331.
Key takeaways
- For the IV placement example, a sample of 741 produced p-hat ≈ 0.93 and a 99% confidence interval from 0.9056 to 0.9540, with a margin of error of 0.0242.
- Holding confidence fixed, increasing sample size lowers standard error and narrows the interval; increasing n from 741 to 2,000 lowered the example’s standard error from 0.009384 to about 0.005712.
- Lowering confidence also narrows an interval, but by reducing the critical value and weakening the reliability of the procedure; a confidence level must therefore accompany the interval.
- The central limit theorem says the sampling distribution of y-bar is centered at μ with standard deviation σ/√n, and is approximately normal for large enough samples even when the population is skewed.
- For a population mean, the practical interval uses y-bar ± t* × s/√n because σ is usually unknown and estimating it with s introduces additional uncertainty.
- The t critical value depends on df = n − 1 and approaches the normal critical value as n grows; for 90% confidence with n = 10, df = 9 and t* = 1.8331.
Chapters
- Chapter 13 confidence intervals estimate a population proportion using p-hat and a normal critical value.
- Chapter 14 estimates a population mean using y-bar, a standard error based on s, and a t critical value.
- Quiz 10 is modeled on the Section 13.3 examples; exam three review problems and scheduling instructions are planned for the coming weekend.
- The parameter is the proportion of IV insertions successfully placed on the first attempt at the hospital using its ultrasound protocol.
- For a sample of 741, p-hat is about 0.93 and the standard error is 0.009384.
- At 99% confidence, the margin of error is 2.58 × 0.009384 = 0.0242, giving an interval from 0.9056 to 0.9540.
- A 99% confidence procedure means that about 99 of 100 intervals from repeated samples of size 741 would contain the population proportion.
- Increasing n from 741 to 2,000 reduces the standard error of p-hat from 0.009384 to about 0.005712.
- With confidence level held fixed, the critical value stays the same, so the smaller standard error reduces the margin of error.
- The resulting interval is narrower, reflecting a more precise estimate, though larger samples can cost more and may challenge study conditions.
- Reducing confidence from 99% to 90% reduces the critical value from about 2.58 to 1.645.
- The smaller critical value reduces the margin of error and makes the interval narrower, even though confidence in the procedure has fallen.
- Jacobsen emphasizes reporting the confidence level so readers can distinguish a narrow interval from a highly reliable one.
- A population includes all individuals or objects of interest; a sample is the subset selected for study, ideally through random sampling.
- For quantitative data, n is sample size, y-bar is the sample mean, and s is the sample standard deviation.
- The unknown population parameters are μ, the population mean, and σ, the population standard deviation; y-bar estimates μ and s estimates σ.
- A census can measure population parameters directly, but cost and feasibility make censuses uncommon.
- A sampling distribution records all possible values of a statistic across repeated samples from the same target population.
- Using all ISU students and GPA as an example, each random sample of size n produces a potentially different y-bar.
- Repeated sample means form a distribution centered at the population mean μ, with differences among samples attributable to sampling variability.
- The sampling distribution of y-bar has mean μ and standard deviation σ/√n.
- If the population is normally distributed, the sampling distribution of y-bar is normal for any sample size.
- For a nonnormal population, the sampling distribution becomes approximately normal when n is sufficiently large; n ≥ 30 is presented as a common rule of thumb.
- How large n must be depends partly on the degree of population skew.
- A calculator simulation draws repeated samples from a strongly right-skewed chi-squared population and plots their sample means.
- With sample size 10, the sampling distribution remains noticeably right-skewed; at 20 and 30, it becomes progressively closer to a normal curve.
- At sample size 150, the distribution of sample means appears approximately normal despite the severely skewed source population.
- The demonstration uses repeated samples to make the central limit theorem visible rather than treating it as only an abstract rule.
- A mean interval using z*σ/√n requires knowing σ, which is usually unknown in practical studies.
- Although σ may be known in special standardized settings such as an IQ test, that situation is uncommon.
- Because the sample standard deviation s is observable and estimates σ, the standard error of y-bar is calculated as s/√n.
- For a population mean, the study estimates two parameters: μ with y-bar and σ with s.
- That extra estimation uncertainty means the normal critical value z* is not appropriate for the usual mean interval.
- The t distribution supplies a critical value that accounts for uncertainty from estimating σ with s.
- The t distribution is symmetric and bell-shaped like the standard normal distribution, but has heavier tails, especially at small sample sizes.
- For a two-sided 95% interval, each tail contains (1 − 0.95)/2 = 0.025; the t critical value must reach farther into the tail than z* when degrees of freedom are low.
- The larger t critical value produces a wider interval to reflect uncertainty in estimating σ.
- The degrees of freedom for a one-sample mean interval are df = n − 1.
- As degrees of freedom increase, the t distribution’s tails become lighter and its shape approaches the standard normal distribution.
- At sample size 30, the t and normal curves are close, though the t critical value remains slightly larger.
- The interval is y-bar ± t* × s/√n, using the sample mean, t critical value, and estimated standard error.
- Conditions include a simple random, representative sample and either a sufficiently large sample, commonly n ≥ 30, or an approximately normal population when n is smaller.
- The t* value depends on the confidence level and n − 1 degrees of freedom.
- For n = 10, the degrees of freedom are 10 − 1 = 9, so the critical value comes from a t distribution with 9 degrees of freedom.
- For a 90% two-sided interval, the left-tail area is (1 − 0.90)/2 = 0.05.
- Using the calculator’s Second, Vars, inverse T function with area 0.05 and df 9 gives t* = 1.8331.
- The corresponding normal critical value would be 1.645, so the larger t* reflects uncertainty from estimating σ; the next class will apply the full interval method.
Transcript excerpt
0:51 And it's official. Welcome back, folks. So we're making a transition now from chapter 13 categorical data into our chapter 14 handling quantitative data. Both topics really are just about confidence intervals. And if we look at the methods to the right, the formulas, the structure in pink is extremely similar. The main difference is the formula is very different if we're talking about the standard error of the sample proportion successes, SEP hat, versus if we're talking about the standard error of the sample means, SE Y bar. Turns out this one's a little bit nicer, faster to compute. Other differences are the critical numbers. This one comes from the normal distribution, but T star is going to come from
1:39 something called the T distribution that we'll be looking into once we go into the chapter 14. So that's where we're at so far. Pretty much the same kind of topics, just different type of data is what's going on in the very next chapter. As far as the quizzes go, quiz number 10, the new one, is pretty much the same as the examples were doing in 13.3. So looking into those is a great model to help out as you're solving the new quiz. But any questions at all to start us out today? Okay, other big announcement is looking forward into the schedule.
2:28 We're getting pretty close to a break. We deserve one. We've been working pretty hard. Before going on break, we're going to finish off our third exam. That way we won't have that hanging over our heads while we're on Thanksgiving break. That's sometimes a better way to run the semester in my opinion. Which means on this Friday, I'm going to be adding the information here, saying exactly what's on exam three, just like
This is the start of the transcript. Save this video free for the whole transcript, searchable and time-coded.
In this course
Related notes
Summary, takeaways, and chapters were generated by AI from the video's transcript and may contain errors. The video belongs to its creator, Mike Jacobsen.