EDF9850_FA1
Overview
Lesa Hoffman reviews course logistics and foundational multilevel modeling, including when clustered data require a two-level model, what ICC1 measures, and why likelihood supports nested-model comparisons. She introduces a homework portal with immediate feedback, new Claude-assisted R functions, and Shiny apps that let students explore multilevel concepts interactively.
Key takeaways
- A two-level model is justified by remaining dependence among people within clusters, not merely by the existence of two treatment groups; patients randomized within one hospital differ from patients nested in treatment- or control-assigned hospitals.
- A multilevel model requires a level-one, person-specific outcome and residual variation across clusters after relevant predictors are included; a jury's collective verdict does not meet the person-level outcome requirement.
- ICC1 quantifies the share of outcome variance between cluster means and within-cluster similarity, but it does not identify the causes of cluster differences.
- A small ICC is not automatically safe to ignore: the between-cluster variance estimate includes a correction involving level-one residual variance divided by cluster size, and adding explanatory predictors can change that correction and increase the ICC.
- Level-two predictors describe clusters, such as school location or principal training, and can explain variation in cluster intercepts; they may also account for cluster differences in level-one slopes.
- Nested models can be compared using the difference in minus-two log likelihood, commonly evaluated as a chi-square likelihood-ratio or deviance test.
Chapters
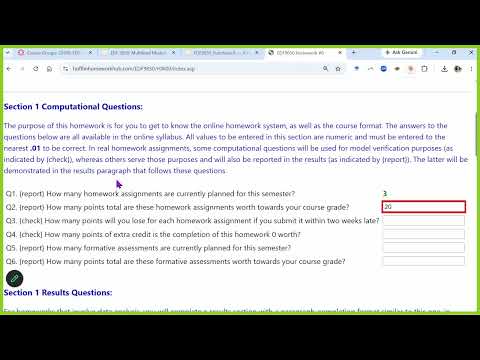
- Homework zero covers the syllabus; students log into the portal using their recorded last name and ID number.
- Computational questions allow repeated attempts and save progress, while multiple-choice interpretation questions allow one attempt and provide feedback after the deadline.
- The portal checks numerical answers at a specified precision, usually 0.01; students can paste full-precision output and upload syntax and results through Canvas.
- Lesa Hoffman created documented R functions with Claude to consolidate repeated multilevel-modeling syntax; the functions are available in a file for homework and analyses.
- Patients randomized to two groups within a single hospital do not automatically constitute multilevel data when a binary group predictor accounts for the design.
- Randomizing 25 hospitals to treatment and 25 to control does create clustering: patients at the same hospital may have more similar outcomes even after treatment status is included.
- In the hospital example, treatment versus control is a level-two predictor, and remaining hospital differences can reveal variation in implementation or treatment fidelity.
- A multilevel model needs a person-level outcome and people nested in clusters with residual cluster variation; a jury-level guilty verdict is not a person-level outcome.
- Ordinary regression, ANOVA, and logistic regression can be fit to clustered data by software, but they wrongly treat people as independent if clustering is ignored.
- ICC1 is the proportion of total outcome variance associated with differences between cluster means, and it also describes the similarity of two people from the same cluster.
- An ICC of zero corresponds to independence under the measure, while an ICC of one means outcomes are entirely alike within clusters.
- Even an ICC near zero is not a reason to ignore clustering: estimating between-cluster variance involves a correction based on level-one residual variance divided by cluster size.
- An ICC of 0.5 means half the outcome variance lies between clusters; it does not explain why some clusters have higher means than others.
- Cluster-level predictors, such as whether a school is rural or urban or a principal's training, can explain differences in cluster intercepts.
- A level-one predictor can reduce residual variance and thereby reduce the ICC correction factor, so the estimated random-intercept variance and ICC can rise after adding predictors.
- Level-two predictors may also explain differences in level-one slopes, although Hoffman notes that this topic comes later in the course.
- Likelihood represents how tall, or plausible, the observed data are under a model; maximum likelihood estimates parameters that make the data most likely.
- Nested models can be compared by testing whether added terms, such as a random intercept, improve fit enough to justify their complexity.
- The difference in minus-two log likelihood is commonly tested against a chi-square distribution and is also called a deviance test or likelihood-ratio test.
- Software packages display likelihood statistics differently, so Hoffman's R functions label both forms to clarify which direction indicates better fit.
- Students download the Activity 1 ZIP from Canvas and work individually or in groups using one of 15 Canvas groups.
- A Google Doc with 15 tabs provides a live collaborative alternative for entering activity answers.
- The activity uses R packages lme4 and nlme; students with outdated R versions can try campus CU Apps for a more recent RStudio environment.
- Hoffman previews the class's Kickstart My Heart theme song and transitions from the review into hands-on work.
- Students launch the first interactive app with its Run App button and can change the ICC setting before selecting simulate and fit.
- The activity asks students to manipulate app inputs and observe how the resulting visualization changes, reinforcing abstract multilevel concepts.
- If the pacman package is missing, students need to run the setup code that installs and loads required packages; Hoffman offers to troubleshoot installation problems.
Transcript excerpt
0:00 All right, I'm officially recording and I say welcome back everybody. Rumors, zoomers, everyone. Thanks for coming back. I should just go with that, right? I didn't scare you off after the first class. That sometimes happens, but you know, you never know. Um, I've been busy, so I've been doing a whole bunch of stuff for this class that I wanted to make sure that I point out because there's some new stuff on the web page. So, first off, I put up the online homework system today. And that is one of the things that you get to work on this coming week is to complete homework zero, which is over the syllabus. And in here, I have a video demonstrating it. But this is where you will go to log into your stuff. Your last name, as it's either in Canvas or on the survey that I gave you, what you wanted to be called.
0:49 So, if it deviated, I went with what you wanted. If you have a hyphenated last name or two last names with a space, that's what you would enter. It is not case sensitive. And then your ID number after that. And I will just do a dummy login here because I have several of those. >> Sorry. Are we supposed to be seeing your screen on Zoom? >> Wouldn't that be nice? >> I just didn't know. I just wanted to say >> you did. You did know. And you are 100% correct. There. I just wanted to see all of y'all. I didn't want to see my screen share. You see? So, you just your windows just get so tiny I get lonely. There we go. All right. So, homework zero. I have a video demonstrating this that takes all of 13
This is the start of the transcript. Save this video free for the whole transcript, searchable and time-coded.
In this course
Related notes
Summary, takeaways, and chapters were generated by AI from the video's transcript and may contain errors. The video belongs to its creator, Lesa Hoffman.