EDF9850_Example5b_Part1
Overview
Lesa Hoffman uses simulated, slightly unbalanced four-occasion data from 200 children to demonstrate how to model depression change over time while separating within-person change from between-person differences. In R, she compares an empty model, a saturated means and unstructured covariance model, and random-slope growth models using lme4 and nlme; the data support an average depression increase of about 0.9 points per year with individual differences in change, but not quadratic growth or additional residual autocorrelation.
Key takeaways
- With longitudinal predictors that vary both within and between children, person-mean centering separates typical gaming levels from occasion-specific deviations and prevents the two effects from being conflated.
- An ICC of 0.45 for depression means about 45% of observed variance lies between children, while the remaining variation occurs across occasions within children.
- A random linear time slope models more than individual differences in average growth: it also implies quadratic change in variance and nonconstant correlations across time.
- The simulated data support an average depression increase of approximately 0.9 points per year, but the random-slope distribution indicates that some children may decrease rather than increase.
- When assessment times are irregular, comparing model-implied means and variances with a saturated benchmark is informative, but rounding time limits how definitive that comparison can be.
- Additional AR(1) residual correlation should be tested rather than assumed: in this example its estimated adjacent correlation is only 0.1 and the likelihood-ratio test does not support retaining it.
Chapters
- The simulated sample contains 200 children measured on four occasions, with assessment times varying by about one-third of a year around the intended annual schedule.
- Hoffman separates baseline age, representing cross-sectional age differences, from time in study, representing longitudinal aging.
- She person-mean centers daily gaming hours to distinguish each child's typical gaming from occasions when the child games more or less than usual.
- Spaghetti plots show average depression rising with age while gaming remains comparatively stable; time is current age minus age at baseline.
- The empty multilevel model treats occasions as level 1 and children as level 2, separating within-child from between-child depression variation.
- The intraclass correlation is about 0.45, meaning roughly 45% of depression variance is between children and repeated observations from the same child have an average correlation of 0.45.
- The ICC is a useful starting summary, but it cannot distinguish systematic change over time from occasion-to-occasion fluctuation.
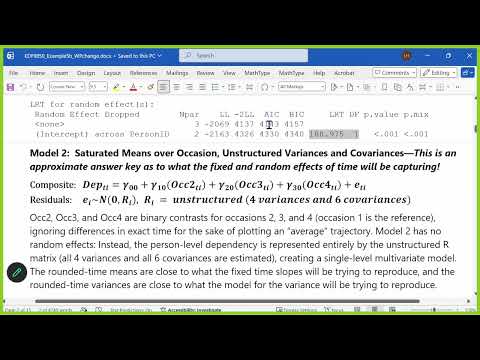
- Hoffman introduces a saturated means model that treats occasion as categorical, estimating a mean for each of the four rounded assessment occasions.
- An unstructured covariance matrix estimates a separate variance for each occasion and a separate covariance for every pair, providing a flexible benchmark for growth models.
- The approach is related to multivariate repeated-measures ANOVA and MANOVA, but likelihood estimation makes model comparisons possible.
- Rounding time into narrower intervals may help reveal nonlinear patterns in irregularly timed data, provided enough observations fall in each interval.
- Hoffman fits the single-level multivariate model with nlme::gls, using occasion-specific variances and unstructured correlations rather than random effects.
- The omnibus F test shows mean differences across occasions; estimated depression means rise from about 8 at occasion one to approximately 0.9 points higher at occasion two and 1.7 higher at occasion three.
- The unstructured estimates show occasion-to-occasion variances changing over time and correlations ranging from about 0.40 to 0.62.
- Changing variance suggests individual trajectories may diverge, while stronger correlations for nearer occasions suggest a time-decaying correlation pattern.
- The random linear time model estimates a fixed time slope and child-specific random slopes, with time zero at each child's baseline assessment.
- Average depression increases significantly by about 0.9 points per year, and the random time slope is also significant.
- The spread of the random slopes includes both increasing and decreasing trajectories, so the average rise does not mean every child worsens.
- A negative intercept-slope correlation indicates that children starting with higher depression tend to have smaller increases or greater decreases.
- Hoffman compares the random linear model's implied means and variances with estimates from the saturated model because irregular timing prevents a clean balanced-data test.
- A random linear slope produces quadratic change in variance over time, creating a U-shaped pattern as children with different slopes spread apart.
- The model also generates nonconstant correlations across occasions, and its predicted means and variances appear reasonably close to the saturated estimates.
- A random quadratic model is tried, but its quadratic slope is not significant; lme4 reports a convergence error, while nlme's lme fit gives similar estimates and supports dropping the quadratic term.
- Balanced assessments can occur in tightly scheduled pretest and posttest designs, but school testing windows often span weeks and should be acknowledged as a limitation when exact dates are unavailable.
- Hoffman adds a continuous-time AR(1) residual structure with nlme::lme and corCAR1, using actual elapsed time to accommodate irregular assessment spacing.
- The estimated adjacent-residual correlation is about 0.1, with correlations declining further for observations two or three years apart.
- A likelihood-ratio test finds the added residual correlation nonsignificant, so the simpler random-intercept and random-time-slope model is retained.
- Unlike a random-intercept-only model, a random linear time slope already creates nonconstant correlations, reducing the need for extra residual correlation in these data.
Transcript excerpt
0:00 We'll start it up again. We'll go for a little bit and then we'll see when we need to break, okay? It's only 5:43, which is usually early, but who knows? So, I was saying before class, these data are simulated. They're simulated based on real data, but they're still fake. And I wrote a book chapter that was just published this year, and the point of the chapter was to show how the same models can be thought of and estimated as univariate multilevel models, single-level structural equation models, and multilevel structural equation models, because even though those are three different ways to accomplish some of the same goals, and there's some direct equivalencies, they look very different. And so, that was the goal of the chapter. I'm just focusing on the univariate multilevel aspect, but that chapter is on your reading list. It's not on the like the
0:49 syllabus, but it's in that doubt that folder that's on Canvas. And on my website is a supplemental appendix that has all the model syntax and code in I think I want to say every package I know of. Certainly R, but also Stata, SAS, and probably SPSS to some extent, too. So, lots of resources there if you care. But, the story for this is we've got four occasion data of children who varied in age at baseline, and they weren't able to get them exactly 1 year apart as typically happens in longitudinal data. So, I simulated that to have some variability. Age varies about a third of a year around where it was supposed to be. So, there's that. So, in this case, we would typically think of time as something that is
1:36 purely within persons if you have a balanced design, but that's not going to
This is the start of the transcript. Save this video free for the whole transcript, searchable and time-coded.
In this course
Related notes
Summary, takeaways, and chapters were generated by AI from the video's transcript and may contain errors. The video belongs to its creator, Lesa Hoffman.