Applied Probability - F26 - Lecture 8
 Watch on YouTube →
Overview
Arash Amini develops two core measure-theoretic tools for probability: Radon–Nikodym derivatives, which express dominated measures through densities, and product measures, which formalize joint distributions and independence. He connects these constructions to likelihood ratios, Tonelli and Fubini integration, tail-integral formulas for expectations, marginal densities, and tests for independence.
Key takeaways
- A measure μ has a density relative to ν exactly when μ is absolutely continuous with respect to ν; the derivative dμ/dν is unique only up to ν-null sets.
- Likelihood ratios compare two dominated distributions: when both have densities against a common measure, dP₁/dP₀ is the ratio of those densities wherever the denominator is positive.
- A product measure is uniquely determined by its values on rectangles, with (μ₁ × μ₂)(A × B) = μ₁(A)μ₂(B).
- Tonelli allows integration in either order for nonnegative functions, while Fubini requires integrability; the distinction determines when swapping integrals is valid.
- For every nonnegative random variable X, E[X] = ∫₀∞ P(X > t) dt, linking the mean directly to the distribution's tail probabilities.
- Independence means factorization across events in the variables' sigma-algebras, and it implies both a product joint distribution and factorization of expectations of functions of separate variables.
Chapters
- Given a measure ν and a nonnegative measurable function f, define a new measure by μ(A) = ∫A f dν.
- The integration identity ∫g dμ = ∫gf dν extends from indicator functions to simple functions and then to nonnegative or integrable functions.
- A standard normal probability measure is obtained by weighting Lebesgue measure with the Gaussian density.
- A measure μ is absolutely continuous with respect to ν when every ν-null set is also μ-null.
- A point mass cannot have a density with respect to Lebesgue measure because a singleton has Lebesgue measure zero but positive point-mass measure.
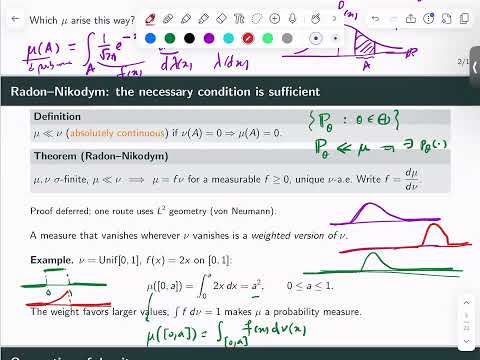
- The Radon–Nikodym theorem says μ = fν for a measurable nonnegative f, unique ν-almost everywhere, when μ is absolutely continuous with respect to ν.
- If two measures have densities f₁ and f₂ against a common reference measure, μ₂ is absolutely continuous with respect to μ₁ when f₂ vanishes wherever f₁ vanishes, up to null sets.
- Mutually singular measures concentrate their mass on disjoint sets, while domination ensures a Radon–Nikodym derivative exists.
- Classical statistical models often assume one fixed reference measure dominates every parameterized probability distribution.
- The uniform measure on [0,1] has density 1 on that interval and 0 outside it with respect to Lebesgue measure.
- Weighting the uniform measure on [0,1] by f(x) = 2x produces a probability measure because ∫₀¹ 2x dx = 1.
- For 0 ≤ a ≤ 1, the resulting measure of [0,a] is ∫₀ᵃ 2x dx = a².
- With counting measure on a countable support, the Radon–Nikodym derivative is the probability mass function.
- With Lebesgue measure as reference, an absolutely continuous real-valued distribution has a probability density function, and P(X ∈ A) = ∫A f(x) dx.
- Lebesgue integration applies to general measurable functions and supports limit theorems such as monotone convergence, unlike the more limited Riemann integral.
- When μ₂ is absolutely continuous with respect to μ₁, its density relative to μ₁ can be computed as f₂/f₁ when both measures have densities against a common reference measure.
- For a standard normal distribution and an exponential distribution, the exponential law is absolutely continuous with respect to the normal law because the normal density is positive everywhere.
- The reverse derivative fails because the exponential density is zero on negative values where the normal distribution assigns positive probability.
- A mixture of a point mass at 0 and a uniform distribution on [1,2] combines discrete and continuous probability mass, so it has no density with respect to Lebesgue measure alone.
- The mixture does have a density relative to a reference measure that includes both its atom and its continuous component, showing that density existence depends on the chosen reference measure.
- For dominated probability measures P₁ and P₀, expectations satisfy ∫h dP₁ = ∫h(dP₁/dP₀) dP₀, the integration identity behind likelihood-ratio methods.
- For a set C in a product space, its section at x is Cₓ = {y : (x,y) ∈ C}.
- Sections preserve set operations such as unions and intersections, and sections of measurable rectangles are either the second component or the empty set.
- These properties help establish that x ↦ μ₂(Cₓ) is measurable for product-measurable sets C.
- Define the measure of C by integrating the measure of its sections: (μ₁ × μ₂)(C) = ∫ μ₂(Cₓ) dμ₁(x).
- Measurability of x ↦ μ₂(Cₓ) makes this definition well-defined; section properties and monotone-class arguments extend it from rectangles to the product sigma-algebra.
- Countable additivity follows by applying integration to disjoint sections, giving a measure on the product space.
- For a measurable rectangle A × B, the construction gives (μ₁ × μ₂)(A × B) = μ₁(A)μ₂(B).
- Rectangles generate the product sigma-algebra, so the π-λ theorem establishes uniqueness of a measure with those rectangle values.
- For probability distributions Pₓ₁ and Pₓ₂, their product measure assigns P(X₁ ∈ A, X₂ ∈ B) = P(X₁ ∈ A)P(X₂ ∈ B).
- Tonelli's theorem permits either order of integration for a nonnegative product-measurable function, including when the integrals are infinite.
- Fubini's theorem permits order-switching for an integrable function, with absolute integrability checked through ∫|f| d(μ₁ × μ₂).
- The product-measure construction proves the result first for indicators of measurable sets, then extends it to simple functions and nonnegative functions.
- For X ≥ 0, write X(ω) = ∫₀∞ 1{t < X(ω)} dt and integrate over the sample space.
- Tonelli's theorem swaps the time and probability integrals to give E[X] = ∫₀∞ P(X > t) dt.
- The same indicator-integral method can express moments such as E[Xᵖ] using tail probabilities, making it useful when tail bounds are available.
- If (X,Y) has a joint density f(x,y) with respect to product Lebesgue measure, its marginal density for X is fX(x) = ∫ f(x,y) dy.
- Integrating out Y follows from Tonelli or Fubini and yields the probability that X lies in a set by integrating fX over that set.
- For a uniform joint distribution on a triangular region, the marginal density is found by integrating the constant joint density across the available vertical section.
- Sigma-algebras are independent when probabilities of intersections of events, one from each sigma-algebra, factor into products.
- Random variables X and Y are independent when σ(X) and σ(Y) are independent; it is sufficient to check the factorization on generating sets such as half-lines.
- Independent random variables have a joint distribution equal to the product of their marginal distributions, and expectations factor as E[h(X)g(Y)] = E[h(X)]E[g(Y)] when the expectations are defined.
Transcript excerpt
0:02 countably additive. Um so you can verify countable additivity via the the MCT and then um this allows you to also integrate with respect to this measure. So if you have a measure we can integrate with respect to it. The question is that if I integrate G with respect to this how should I do it? There is an easy way of doing it. that you can integrate with respect to the other one by just multiplying g by f. Okay, so these are kind of um intuitive. Um and to verify this you can verify it for first um like this holds for any non- negative function measurable function or anything in L1 you use the standard machine. So you apply to indicators first then to
0:51 all simple functions all non- negative functions and then by splitting into positive and negative into like like the L1 functions. Okay. And then um the question is that so this gives you a very easy way to generate lots of measures. For example, if this is a labbe measure this density would be a function on R. So for example, if you have the Gaussian density, right? So it's like an example would be right. So this is the like a gausian density. So you would say I I define a measure which is like integral 1 2 pi e to the negative. Let's do it with with just
1:38 um standard normal. So everyone knows the standard normal x^2 / 2 dx / a. Okay. So this defines the gausian measure. Okay. It's the distribution of a gausian random variable. So this dx here here is like if you want it's like d um lambda x or if you want you can write it as um lambda dx. Okay. So this is the
This is the start of the transcript. Save this video free for the whole transcript, searchable and time-coded.
Related notes
Summary, takeaways, and chapters were generated by AI from the video's transcript and may contain errors. The video belongs to its creator, ARASH AMINI.