Applied Probability - F26 - Lecture 10
 Watch on YouTube →
Overview
Arash Amini develops conditional expectation as the L2 projection of a random variable onto the space measurable with respect to a sigma algebra, deriving orthogonality, contraction, and the tower and variance decomposition properties. He connects this geometry to regression and empirical risk minimization, works through a nonlinear example with X = Y² + ε, and introduces conditional distributions as Markov kernels.
Key takeaways
- For square-integrable X, E[X | G] is the unique L2(G) predictor whose residual is orthogonal to every G-measurable square-integrable variable.
- The indicator identity E[E[X | G]1_A] = E[X1_A] for A in G characterizes conditional expectation and immediately gives the law of total expectation.
- With Y uniform on [−1, 1] and X = Y² + independent mean-zero noise, E[X | Y] = Y², while the best linear predictor is only the constant 1/3.
- Empirical regression approximates population squared-error minimization, but unrestricted function classes can interpolate a finite sample and overfit.
- Nested sigma algebras yield the tower property because projecting first onto a larger information space and then a smaller one equals direct projection onto the smaller space.
- The variance identity Var(X) = Var(E[X | G]) + E[Var(X | G)] separates variation explained by observed information from remaining uncertainty.
Chapters
- After brief audio setup, Arash Amini frames prediction of X using information in Y, represented by the sigma algebra generated by Y.
- The conditional expectation is the element of L2(G) minimizing the L2 distance to X, where G is the conditioning sigma algebra.
- The projection exists because L2(G) is a closed linear subspace, and it is G-measurable by construction.
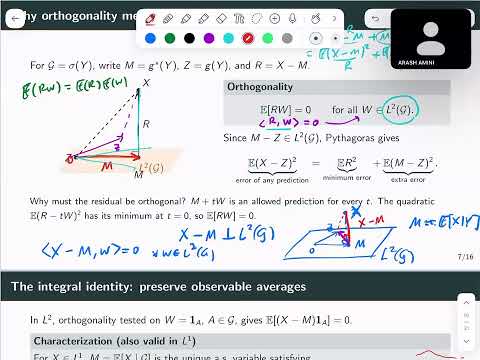
- For M = E[X | G], the residual X − M is orthogonal to every W in L2(G).
- For any alternative Z in L2(G), the Pythagorean identity gives ||X − Z||² = ||X − M||² + ||Z − M||².
- The identity proves M is the unique closest point in L2(G), and the orthogonality condition also characterizes the projection.
- Choosing W = 1_A for A in G yields E[M1_A] = E[X1_A], the standard integral characterization.
- The indicator identity extends from indicators to simple functions and then to broader classes of functions.
- For X in L1, conditional expectation is characterized as a G-measurable L1 variable satisfying this identity, unique almost surely.
- The projection operator P_G is linear and contracts L2 distances: projecting X1 − X2 cannot increase its norm.
- Taking A = Ω in the indicator identity gives E[E[X | G]] = E[X].
- When G = σ(Y), Doob-Dynkin factorization represents E[X | Y] as g*(Y), with g* defined up to sets of probability zero under Y's distribution.
- The function g* is the regression function and remains well-defined even when individual values of Y have probability zero.
- The regression function minimizes E[(X − g(Y))²] over square-integrable functions g of Y.
- This optimization interpretation identifies conditional expectation as the best mean-squared-error predictor using Y.
- Amini relates the population objective to statistical estimation from an IID sample of pairs (X_i, Y_i).
- The law of large numbers motivates replacing E[(X − g(Y))²] with the sample average of (X_i − g(Y_i))².
- Minimizing this empirical risk over every possible function can overfit by matching each observed X_i to its Y_i.
- Restricting the candidate class, for example to continuous or linear functions, trades flexibility against generalization.
- Linear regression is the empirical-risk solution within functions of the form a + bY, while unrestricted regression can be nonlinear.
- Amini considers Y uniform on [−1, 1] and X = Y² + ε, with ε square-integrable, independent of Y, and mean zero.
- The candidate conditional expectation is Y² because it is a function of Y and the residual X − Y² equals ε.
- For every square-integrable g(Y), E[εg(Y)] factors by independence and is zero, verifying the projection orthogonality condition.
- Linearity, the fact that Y² is known given Y, and independence provide a shorter calculation of E[X | Y] = Y².
- A population L2 comparison, E[(g_hat(Y) − g*(Y))²], evaluates a fitted function on a fresh Y independent of the training sample.
- Because the score integrates over Y's distribution, changing a regression function on a probability-zero set does not change this error.
- A test sample of M new points can approximate the population error through its average squared prediction error.
- Pointwise convergence at a specific Y can be harder to establish than average prediction performance.
- For X = Y² + ε with symmetric uniform Y on [−1, 1], the best linear predictor a + bY is the constant 1/3.
- Symmetry gives slope b = 0, while E[Y²] = 1/3 determines the intercept.
- The nonlinear predictor Y² achieves no greater squared error than the restricted linear predictor, and can do strictly better.
- Linearity, monotonicity, and the pull-out rule for bounded G-measurable factors follow from the conditional expectation characterization.
- If X is already G-measurable, E[X | G] = X; if X is independent of G, E[X | G] = E[X].
- Conditioning a fair die roll X on its parity gives 3 on odd outcomes and 4 on even outcomes.
- The indicator formulation lets these properties be checked first on events and then extended by approximation.
- For H contained in G, L2(H) is a subspace of L2(G), so conditional expectation onto H can be obtained by projecting E[X | G] onto L2(H).
- The tower property is E[E[X | G] | H] = E[X | H], expressing consistency between nested information sets.
- In the die example, parity and the event X ≥ 4 provide combined information that refines the parity-based partition.
- Conditional expectations on the refined groups can be averaged back to the parity groups, recovering the coarser projection.
- The residual X − E[X | G] is orthogonal to G-measurable quantities, including E[X | G] − E[X].
- The Pythagorean identity yields Var(X) = Var(E[X | G]) + E[Var(X | G)].
- The first term is variation explained by the information in G; the second is the expected remaining conditional variance.
- Adding information enlarges the prediction subspace and cannot increase the minimum expected squared prediction error.
- A conditional probability can be defined through a conditional expectation: P(X ∈ A | G) = E[1_{X ∈ A} | G].
- For each event A, this quantity is a G-measurable random variable defined only up to almost-sure equality.
- Choosing versions consistently across all sets A is necessary for the event argument to satisfy the axioms of a probability measure.
- The resulting object K(y, A), measurable in y and a measure in A, is a Markov kernel representing a conditional distribution.
Transcript excerpt
2:00 Uh, yes. Okay. This should be Now I think I have hearing my own voice. So it shouldn't Okay. Okay. Uh So where is it? Right. Okay. So um the general idea is that you have a random variable or let's say X and you want to predict based on Y uh or more generally based on the information provided by Y. So so we can generalize this to projecting or like predicting based on a sigma algebra. And I mean in in in the case where uh Y is a random variable, we're looking at the sigma algebra generated by Y.
2:47 And so what we get is this idea of projection. So when I look at all the random variables that are in L2 of G uh I look at the one that's closest to X in the L2 norm. So you can think of this as also argmin. It's the same as X minus Z L2. If you remember, I mean this is L2 squared but argmin doesn't care about the square so I can write it like this. Z is in L2 of G. It's really a projection operation. So you think of this as a vector. It varies in this linear space and this is another vector and I'm finding the closest X is generally in general not in L2. It's not measurable with respect to G.
3:34 Uh it's not completely determined by the information in G and so I want to find the closest Z in there. And so this gives me um uh a nice definition of this. This is going to be G measurable by definition because it's in there and it's also in L2. Um and exists by by by the fact that this is a closed linear subspace. Um but anyways, the the key is that
This is the start of the transcript. Save this video free for the whole transcript, searchable and time-coded.
In this course
Related notes
Summary, takeaways, and chapters were generated by AI from the video's transcript and may contain errors. The video belongs to its creator, ARASH AMINI.