UUtah Data Mining | Fall 2026 | L18: RandProj
 Watch on YouTube →
Overview
The lecture connects learned Mahalanobis distances to dimensionality reduction, showing how a positive semidefinite metric can be factored and truncated to create a lower-dimensional Euclidean representation. It then presents random projections and the Johnson-Lindenstrauss lemma: for n points, a randomized map into roughly O(ε⁻² log(n/δ)) dimensions preserves every pairwise distance within a factor of 1 ± ε with failure probability at most δ.
Key takeaways
- A positive semidefinite Mahalanobis matrix M can be factored as AᵀA, turning its distance into Euclidean distance after a linear embedding.
- Truncating M to its top k eigenvectors creates a k-dimensional representation, but whether that representation retains the important information depends on the metric and data.
- Supervised metric learning depends on trustworthy close and far pairs; the lecture recommends at least roughly d pairs, ideally two to three times d for each type.
- The Johnson-Lindenstrauss lemma preserves all pairwise distances among n points within 1 ± ε using a dimension on the order of ε⁻² log(n/δ).
- A random projection can be implemented by Gaussian-sampled unit directions, dot products, and scaling by √(d/k); its all-pairs guarantee comes from concentration plus a union bound.
Chapters
- Homework 5 covers dimensionality reduction using two datasets, PCA through SVD, LDA, and multidimensional scaling; it is due in one week.
- Project groups should bring printed intermediate reports to their scheduled meetings and arrive on time to receive feedback.
- The lecture plan is to finish learned Mahalanobis distance, introduce random projections, then move into project peer feedback.
- For points x₁ and x₂, the Mahalanobis distance is √((x₁ − x₂)ᵀM(x₁ − x₂)), where M is a d × d matrix.
- Setting M to the identity gives ordinary Euclidean distance; a learned M can adjust coordinate scales and account for correlated features.
- A learned metric is useful when raw Euclidean distance is unreliable, such as when features have mixed units.
- For positive semidefinite M, an eigendecomposition M = VΛVᵀ gives a factorization M = AᵀA.
- Truncating to the top k eigenvectors and eigenvalues forms a rank-k metric Mₖ and an embedding into a k-dimensional subspace.
- After applying the factor Aₖ to each point, Mahalanobis distance in the original space becomes Euclidean distance between the embedded points.
- Metric learning is supervised: it uses labeled close pairs and far pairs to determine which distances should shrink or grow.
- LDA supplies one source of pair labels: same-class points are close, while points from different classes are far.
- Pairs can also come from repeated observations or language-model embeddings, where words or contexts known to be related should remain close.
- LDA uses within-class and between-class covariance to favor small within-class distances and separation between classes.
- IDML is described as a relatively simple gradient-descent method; another linked method models noise, and the homework bonus explores an additional approach.
- Metric learning needs enough reliable pair labels: the guidance is at least on the order of d, preferably two to three times d for both close and far pairs.
- Adding more pairs can improve generalization, but only when confidence in the labels remains adequate.
- Random projections target extremely high-dimensional data, with examples around d = 10 million and output dimensions in the hundreds to roughly 1,000.
- For every pair in a set of n points, the projected distance is required to lie between (1 − ε) and (1 + ε) times the original distance.
- The Johnson-Lindenstrauss lemma gives a target dimension on the order of ε⁻² log(n/δ) for failure probability δ.
- At ε = 0.1, the ε⁻² term alone is 100; the strong all-pairs guarantee generally requires more dimensions than a PCA embedding optimized for overall variance.
- Choose k random unit vectors u₁ through uₖ in ℝᵈ and map x to their dot products with x.
- The lecture scales the k projected coordinates by √(d/k) to compensate for the typical shrinkage caused by projection.
- Generate each direction by sampling a d-dimensional standard Gaussian vector and normalizing it; Gaussian sampling produces an isotropic random direction.
- The resulting map is a simple randomized computation that can be reused on new data points.
- For a fixed difference vector z, isotropy gives E[(z · u)²] = ‖z‖²/d for a uniformly random unit direction u.
- Averaging k projected squared components and scaling by d/k gives an unbiased estimate of ‖z‖².
- Concentration bounds control how far this estimate deviates from the true length; a union bound extends the guarantee across all pairs.
- The lecture identifies the resulting dimension dependence as ε⁻² log(n/δ), while skipping the full concentration proof.
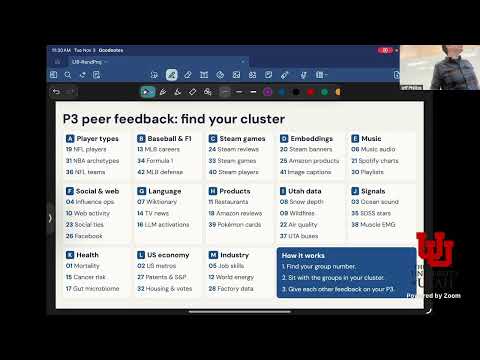
- Students locate their assigned groups using group letters and numbers mapped to positions in the room.
- Groups take turns reading other teams’ intermediate reports and giving feedback, with note-taking encouraged.
- The instructor checks that all groups are present while students exchange project feedback.
Transcript excerpt
0:22 Welcome back everyone. So, let's get started. Um, oh, actually we should we should wait till I turn on the projector. All right. Um uh that's great. So uh um thanks for coming in person. Uh so today for the second half the lecture we're going to do peer feedback on your projects and then I'm going to get to meet with all of you over the next week. I'm very excited to see the the progress you've made on everything. Um so the first half of the lecture will be on the dimensionality reduction topic. We're going to first cover a little bit about getting back to learning
1:13 a mahalonobus distance that we didn't quite wrap up at the end of last lecture. And then we'll talk about oh random projections which are kind of a core technique in dimensional reduction but I'm not going to spend too long on them because they're the the kind of the the short thing is they're only going to work from like ridiculously high dimensions down to like few hundred dimensions where that's the the target. So the application is less for kind of visualization easy to use and more for you really need to kind of kind of compress a ridiculously high representation of your data. Um so okay before we get started just um so um um so let me say um the homework five
2:07 has been posted on dimensionality reduction. It is due in so one week you should have everything you need to run the assignment. Um the there are two data sets you'll use there. Um this is linked off the web page. Now you'll turn everything is everything else in on canvas. Um the actual coding should be pretty straightforward but um so but there's there's a I added a little bit
This is the start of the transcript. Save this video free for the whole transcript, searchable and time-coded.
Related notes
Summary, takeaways, and chapters were generated by AI from the video's transcript and may contain errors. The video belongs to its creator, UofU Data Science.