Math317Fa26 Lec04 DimCalcIntroLinProg
 Watch on YouTube →
Overview
Steven Miller introduces linear programming by connecting optimization to the choice of a useful objective, the limits of local optimization, and the need to model real constraints accurately. He develops fractal dimension from Pascal's triangle, reviews calculus-based optimization, and formulates a diet problem as minimizing food costs subject to minimum iron and protein requirements, leading to the linear program maximize or minimize cᵀx subject to constraints such as Ax ≤ b and x ≥ 0.
Key takeaways
- A useful optimization model starts by specifying what success means and over what time horizon; a company may maximize profit while a sports franchise may value a championship more than cost.
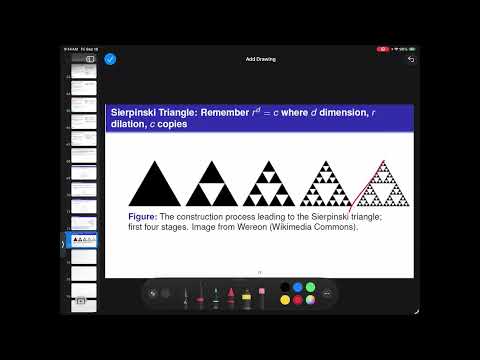
- The Sierpinski triangle has fractal dimension log base 2 of 3 because doubling its scale produces 3 self-similar copies, placing its dimension strictly between 1 and 2.
- A zero derivative identifies a candidate for an interior extremum, not a guaranteed maximum or minimum; f(x) = x³ has a stationary point at 0 but no extremum there.
- Local optimization can miss the global best: a dog may travel to shore and run because the faster land route beats swimming directly, and numerical searches can compare results from many starting points.
- A diet linear program minimizes total food cost while meeting minimum nutrient requirements; its decision variables are food quantities, its objective coefficients are prices, and its constraints encode iron and protein needs.
- Model reliability depends on input quality and sensitivity: a detailed equation is not useful when its parameters are unavailable, and small changes can substantially alter predictions in unstable systems.
Chapters
- Miller argues that applying a familiar method to an unfamiliar problem can add value, especially when collaborating across fields.
- A business may maximize profit, while a sports franchise may prioritize winning a championship; the objective and time horizon change the optimization problem.
- He uses the distinction between batting average and on-base percentage, including walks, to show how choosing a better statistic changes evaluations.
- Marking odd entries and removing even entries in Pascal's triangle reveals a self-similar pattern related to the Sierpinski triangle.
- Because each Pascal entry is the sum of two entries above it, parity can be computed using remainders modulo 2 rather than storing full binomial coefficients.
- Miller emphasizes tailoring code to its purpose: a program that draws the pattern efficiently may not retain enough information to report a specific row later.
- For an object that produces C copies when scaled by a factor R, Miller defines dimension D through C = R^D.
- The rule gives dimension 1 for a line and dimension 2 for a square: doubling the scale produces 2 and 4 copies, respectively.
- The Sierpinski triangle produces 3 copies when doubled, so its dimension is log base 2 of 3, strictly between 1 and 2.
- Miller assigns a Cantor set dimension problem and suggests a separate extra-credit challenge: construct and justify a half-derivative whose repeated application yields an ordinary derivative.
- Miller's fictional foods, spoo and gagh, illustrate that a diet objective should meet minimum iron and protein needs, not maximize nutrient intake without limit.
- A model with 46 variables may be elegant but useless if a company cannot measure its own parameters, much less competitors' values.
- The pendulum example distinguishes stable equilibrium at the bottom from unstable equilibrium at the top, illustrating how small parameter changes can matter greatly in sensitive models.
- Miller reviews derivative definitions using limits and explains differentiability as a strong local linear approximation, not merely the existence of partial derivatives.
- For a differentiable multivariable function, the gradient provides the linear approximation; the remaining error becomes small faster than the distance to the point.
- A local maximum or minimum at an interior point requires a zero derivative, but a zero derivative is only a candidate: f(x) = x³ has f′(0) = 0 and no maximum or minimum there.
- The first-derivative sign test can rule out extrema by checking whether the function rises or falls on either side of a stationary point.
- A dog retrieving a stick may swim to shore, run on land, and reenter the water instead of taking the locally direct route, because it can run faster than it swims.
- The optimal route depends on the relative speeds in water and on land, much like refraction and Snell's law in physics.
- Miller warns that gradient-based flow can reach a local maximum rather than a global one; starting from many random points and comparing results is one practical strategy.
- In the initial food table, gagh dominates spoo on nutrients per dollar, so the choice is obvious regardless of the required iron and protein amounts.
- After spoo's price falls from $20 to $4 per unit, it provides more iron per dollar while gagh still provides more protein per dollar.
- Depending on the required nutrient amounts, the least-cost diet may use only one food or a mixture; extreme requirements help predict which solutions are plausible.
- Unlike a square, invertible system Ax = b, real-world models often have fewer equations than unknowns and therefore many feasible solutions.
- Linear programming represents requirements with matrix constraints such as Ax = b or Ax ≤ b.
- A less-than-or-equal constraint can be converted to an equality by adding a nonnegative slack variable that records unused capacity.
- The diet variables x represent quantities of spoo and gagh, while the cost vector c contains their per-unit prices.
- The objective cᵀx minimizes total cost, subject to enough iron and protein, encoded as linear constraints, and nonnegative food quantities.
- Maximizing and minimizing are interchangeable by negating the objective: maximizing −f is equivalent to minimizing f.
- Miller closes by noting that linear programming will require new tools beyond the calculus methods reviewed in class.
Transcript excerpt
0:00 Okay, so welcome to 317 operations research. Uh, today's the first day we're going to start really hitting, you know, one of the key units of the class, linear programming. How do you solve some real world problems? One of my favorite quotes of all time is, if all you have is a hammer, pretty soon every problem looks like a nail. There's a couple of ways to interpret this. One is no matter what you're given, you try to find a way to use your hammer. I'm really good at this. I'm going to make it look like that. A better way to look at this is go to the land of the screwdriver. If they could have solved the problem using what they were good at, they would have. And so I've written a huge number of papers and fields outside of mathematics by collaborating with people who've already tried the methods from their fields. And I've been able to apply some number
0:47 theory and some combinatorics in some really strange places because I have a different skill set. If you are competing with people with the same skill set as you, nothing against you, but that's tough odds. If you can take where you have a competitive advantage and move that someplace else, you have value added. So what I want to do today is talk about the basics of linear programming. Why can so many problems be modeled like this? Why can we uh solve a lot of things like this? To really do this justice, in the end of the day, we're going to have to choose something to optimize. This is where there is a lot of challenge, I'll say, in real world applications. For many things, it's pretty easy to figure out what you're
This is the start of the transcript. Save this video free for the whole transcript, searchable and time-coded.
In this course
Related notes
Summary, takeaways, and chapters were generated by AI from the video's transcript and may contain errors. The video belongs to its creator, Steven Miller.