RL @ ECE-UofT - Lecture 06: SARSA Algorithms and Q-Learning
 Watch on YouTube →
Overview
Ali Bereyhi develops model-free control from Monte Carlo methods through on-policy SARSA and off-policy Q-learning, emphasizing how exploration, bootstrapping, and eligibility traces affect learning. The lecture derives importance sampling and the Q-learning max target, compares the algorithms on cliff walking, and closes by motivating function approximation and deep Q-networks for continuous or high-dimensional state spaces.
Key takeaways
- SARSA's target is on-policy: Rₜ₊₁ + γQ(Sₜ₊₁, Aₜ₊₁) uses the next action actually selected by the epsilon-greedy behavior policy.
- Q-learning separates behavior from its target: it explores with epsilon-greedy actions but updates toward Rₜ₊₁ + γ maxₐ Q(Sₜ₊₁, a), estimating greedy action values.
- GLIE requires both repeated exploration of every state-action pair and a policy that becomes greedy in the limit; a fixed epsilon preserves exploration but does not become fully greedy.
- SARSA(λ) uses eligibility traces to distribute each TD error across previously visited state-action pairs, enabling online credit assignment beyond a single Q entry.
- Importance sampling reweights behavior-policy data by target-to-behavior probabilities, but large policy differences can create high-variance estimates.
- Tabular RL scales poorly with continuous or high-dimensional states; function approximation and DQN address this by estimating Q values beyond a finite lookup table.
Chapters
0:00
Model-Free Control: Improving Policies from Sampled Experience
- Model-based policy and value iteration rely on knowing the MDP; model-free control instead estimates action values from sampled interactions.
- Generalized policy iteration alternates evaluation and improvement, but online control can update after just one new sample.
- Epsilon-greedy improvement balances exploitation of the highest estimated action value with random exploration.
5:27
Monte Carlo Control Updates Action Values by Episode
- Monte Carlo control waits for a complete trajectory ending in a terminal state before computing sample returns.
- For each state-action pair on the episode, returns are accumulated backward and used to update its action-value estimate.
- After an episode updates the Q table, epsilon-greedy behavior guides the next episode instead of repeatedly sampling a fixed initial policy.
9:17
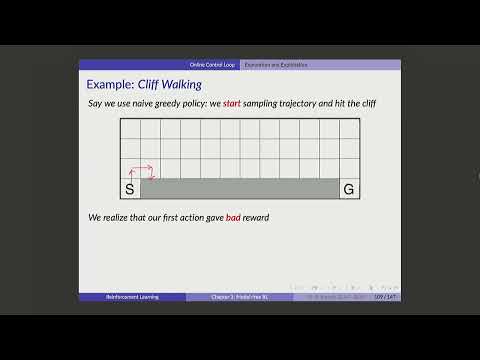
Cliff Walking Shows Why Greedy Exploration Can Fail
- In the cliff-walking grid, the shortest route reaches the destination but risks a severe penalty for falling into the gray cliff.
- A greedy agent can become attached to a safe but longer route after discovering it, leaving better routes unexplored.
- Epsilon-greedy action selection occasionally tests alternatives, allowing the agent to discover and evaluate the shorter path.
15:21
Infinite Exploration Is Needed for Monte Carlo Control
- Accurate action-value estimates require every state-action pair to be visited repeatedly as the number of episodes grows.
- A purely greedy policy can stop visiting alternatives permanently, so additional samples do not guarantee discovery of the optimal policy.
- Persistent exploration supports coverage, but an indefinitely fixed epsilon still causes random, potentially suboptimal actions.
22:02
GLIE Combines Repeated Exploration with Greedy Behavior
- GLIE means Greedy in the Limit with Infinite Exploration: state-action pairs keep receiving visits while the policy becomes greedy asymptotically.
- A practical design starts with larger epsilon and reduces it over time, rather than stopping exploration at a hard episode threshold.
- Under suitable coverage and update conditions, increasingly accurate estimates plus a greedy limiting policy support convergence to optimal control.
27:41
A 1/k Epsilon Schedule Supports GLIE
- The lecture gives epsilon proportional to 1/k, where k counts episodes, as a classic decay schedule.
- The harmonic series sum of 1/k diverges, preserving cumulative opportunities to explore; the sum of 1/k squared is bounded.
- Epsilon can also be reduced periodically, such as multiplying it by a factor below one after several trajectories.
31:07
TD Control Leads to the SARSA Algorithm Family
- Temporal-difference control updates during an episode, avoiding Monte Carlo's need to wait for the terminal return.
- TD(λ) combines information across different return horizons using eligibility traces, aiming to use sampled experience efficiently.
- SARSA is named for the sequence State, Action, Reward, State, Action; TD(0), n-step TD, and TD(λ) yield SARSA variants.
34:37
Deriving the Basic SARSA TD(0) Update
- After taking action Aₜ, the agent observes reward Rₜ₊₁ and next state Sₜ₊₁.
- A first TD target can use Rₜ₊₁ plus the discounted value of Sₜ₊₁, with that state value estimated by averaging Q values under the current policy.
- The update changes the Q estimate for the current state-action pair and then uses the updated estimates to improve behavior.
42:16
SARSA Uses the Action Actually Selected by Its Policy
- Averaging over every next action can be noisy early in learning when most entries in the Q table are still zero or poorly estimated.
- Because the agent samples its next action from its current policy, SARSA can use that known action directly in its target.
- The resulting on-policy target is Rₜ₊₁ + γQ(Sₜ₊₁, Aₜ₊₁), rather than a value averaged over possible next actions.
47:27
SARSA TD(0) Follows the State-Action-Reward Sequence
- At each step, SARSA observes the reward and next state, selects the next action using epsilon-greedy behavior, and forms its target from that action.
- The TD error updates the current Q(Sₜ, Aₜ), after which the agent continues with the selected next action.
- Unlike Q-learning, SARSA's target reflects the exploratory policy the agent is actually following.
50:02
SARSA n-Step Returns and the Forward View of TD(λ)
- An n-step SARSA return adds observed rewards along the sampled on-policy trajectory and bootstraps from a later state-action value.
- The forward view of TD(λ) averages returns across different horizons, from one-step TD through longer returns.
- Computing those returns requires waiting for later trajectory steps, so the forward view adds delay to online learning.
54:17
Eligibility Traces Extend TD(λ) to State-Action Pairs
- SARSA(λ) keeps an eligibility table with one entry for each state-action pair, initialized to zero.
- At each step, traces are decayed by γλ and the current state-action pair's trace is incremented.
- The TD error can then update multiple previously visited Q entries in proportion to their eligibility.
56:28
SARSA(λ) Updates Multiple Q Values Online
- At the start of each episode, SARSA(λ) resets its eligibility table and samples an initial state-action pair.
- Its on-policy TD error is δ = Rₜ₊₁ + γQ(Sₜ₊₁, Aₜ₊₁) − Q(Sₜ, Aₜ).
- Each Q entry is updated using its eligibility trace, so one transition can credit several earlier state-action pairs.
1:03:38
Off-Policy Learning Reuses Data from Another Policy
- Off-policy methods ask whether trajectories generated by behavior policy π can evaluate or improve a different target policy π̄.
- Reusing earlier trajectories can improve sample efficiency after the target policy changes.
- Bereyhi motivates the idea with chess: observing another player's choices can teach useful moves or reveal mistakes without adopting that player's policy.
1:08:27
Importance Sampling Reweights Samples from P to Q
- For a random variable sampled from distribution P, an expectation under Q can be expressed using P-weighted samples multiplied by Q(x)/P(x).
- With K samples, the Monte Carlo estimate of an expectation under Q averages each sample after applying that likelihood ratio.
- The ratio converts samples from a behavior distribution into an estimate for a target distribution, provided the relevant target outcomes are supported by P.
1:14:59
Trajectory Importance Sampling Cancels Shared MDP Dynamics
- For a trajectory generated under π, its probability factors into action-policy probabilities and environment transition probabilities.
- Comparing the same trajectory under target policy π̄ and behavior policy π cancels the shared MDP transition terms.
- The resulting trajectory weight is the product of π̄(Aₜ|Sₜ)/π(Aₜ|Sₜ) across the trajectory.
1:27:02
Importance Sampling Enables Off-Policy Value Estimation
- A return observed under behavior policy π can be reweighted to estimate the value of target policy π̄.
- Large differences between π and π̄ can produce high-variance weights, making off-policy estimates unreliable.
- Importance sampling also motivates reuse of older experience in policy optimization, where constraining policy changes helps control variance.
1:34:31
Off-Policy TD Reweights the Next Action
- For state-value TD, the one-step importance ratio is π̄(Aₜ|Sₜ)/π(Aₜ|Sₜ), because the observed next action was drawn by the behavior policy.
- The environment's transition probabilities cancel when comparing the same transition under the two policies.
- This lets a TD update based on a behavior-policy sample estimate a different target policy's value.
1:37:07
Off-Policy Action-Value TD Keeps the Immediate Reward
- When updating Q(Sₜ, Aₜ), the immediate reward follows the already-observed state-action transition and is not itself reweighted.
- The policy correction applies to the future value, whose action selection is affected by the target policy.
- Separating the immediate reward from the next-state correction avoids incorrectly multiplying the entire target by the importance ratio.
1:43:42
Q-Learning Targets a Greedy Policy While Exploring
- Q-learning uses epsilon-greedy behavior to collect exploratory transitions but learns action values for a greedy target policy.
- The target policy is greedy with respect to the Q table, while the behavior policy can still choose random actions.
- This separation supports exploration without making the learned Q table an evaluation of the exploratory policy itself.
1:51:34
The Q-Learning Max Target Avoids Explicit Ratios
- For a greedy target policy, the next-state value is the maximum Q(Sₜ₊₁, a) over available actions.
- The TD target becomes Rₜ₊₁ + γ maxₐ Q(Sₜ₊₁, a), yielding the standard Q-learning update.
- Because the maximizing action is known from the Q table, the greedy target can be computed directly instead of explicitly multiplying trajectory importance ratios.
1:55:34
Q-Learning Builds the Optimal Q Table from Epsilon-Greedy Data
- The agent chooses Aₜ with epsilon-greedy behavior, observes Rₜ₊₁ and Sₜ₊₁, and updates Q(Sₜ, Aₜ).
- Its target uses the largest next-state action value, corresponding to what greedy behavior would select after the transition.
- Richard Sutton is credited in the lecture for the key Q-learning insight that makes this off-policy update simple.
1:57:38
Q-Learning with Eligibility Traces Uses Q(λ)
- Q-learning can incorporate eligibility traces by maintaining a Q table and a matching trace table.
- Its TD error uses the reward plus γ maxₐ Q(Sₜ₊₁, a), even though the behavior action is epsilon-greedy.
- The lecture notes that traces should be reset when a random exploratory action starts a fresh trajectory segment.
2:01:52
Cliff Walking Contrasts SARSA and Q-Learning
- SARSA evaluates the epsilon-greedy policy it follows, so its learned route accounts for the risk created by exploratory actions near the cliff.
- Q-learning estimates greedy action values while behavior remains exploratory, which can produce lower observed rewards during training.
- A lower training return does not mean the learned Q table is suboptimal: deploying it greedily can yield stronger performance.
2:05:03
Convergence Depends on Coverage and Policy Improvement
- The lecture extends GLIE reasoning to online control: every state-action pair must be visited infinitely often while behavior approaches greedy action selection.
- For SARSA, epsilon can decay with time, for example proportionally to 1/t, while step sizes must also satisfy appropriate stochastic-approximation conditions.
- Convergence claims are asymptotic; large state spaces can make the required visits impractical.
2:11:53
Practical SARSA Tuning Trades Guarantees for Stability
- The Robbins–Monro pattern described in the lecture requires step sizes whose sum diverges while the sum of their squares remains bounded.
- In practical experiments, alpha and epsilon are often tuned as hyperparameters rather than forced to follow an exact 1/t schedule.
- The cliff-walking assignment illustrates sensitivity: decaying epsilon too quickly can lock SARSA into a poor policy.
2:15:36
SARSA and Q-Learning Suit Different Control Goals
- Q-learning offers off-policy learning and can keep exploratory behavior while its Q table targets greedy control.
- SARSA can be preferable when the deployed agent must behave according to the policy currently being learned.
- Eligibility-trace resets and computational cost can also differ, so algorithm choice depends on the application's exploration and online-control requirements.
2:18:15
Tabular RL Breaks Down for Continuous State Spaces
- Tabular methods require countable state and action sets; Bereyhi illustrates the problem with joint angles discretized into bins.
- Even one angle discretized at half-degree resolution can require about 360 states, and multiple body joints multiply the state count.
- The course's next step is function approximation, which estimates Q values beyond the exact state-action pairs seen in a table.
2:20:33
Function Approximation Leads from Tabular Q to DQN
- A linear model or neural network can fit sampled Q values and provide estimates for states and actions not previously observed.
- Deep Q-networks (DQN), introduced by DeepMind, brought neural function approximation into reinforcement learning at scale.
- Bereyhi previews linear approximation and state-action embeddings, noting that one-hot features recover the tabular case.
Summary, takeaways, and chapters were generated by AI from the video's transcript and may contain errors. The video belongs to its creator, Ali Bereyhi.