Mathematical Foundations of AI Alignment, Lecture 2 (Arrows Impossibility Theorem)
 Watch on YouTube →
Overview
Aaron Roth connects Arrow's impossibility theorem to reward modeling in reinforcement learning from human feedback (RLHF): turning ordinal preferences from multiple annotators into one ranking faces unavoidable trade-offs. With at least three alternatives, any aggregation rule satisfying Pareto unanimity and independence of irrelevant alternatives must be a dictatorship, as Roth demonstrates through a pivotal-voter proof; possible alternatives include restricting preferences, changing the aggregation criterion, or working with distributions instead of rankings.
Key takeaways
- A reward model fitted from pairwise human judgments induces a single ranking, so preference aggregation is a core design choice in RLHF rather than a neutral implementation detail.
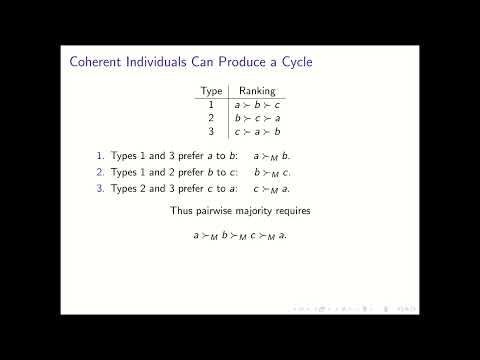
- With three coherent rankings A>B>C, B>C>A, and C>A>B, pairwise majority creates A>B, B>C, and C>A, which no transitive scalar-reward ranking can represent.
- Arrow's theorem states that with at least three alternatives, Pareto unanimity plus independence of irrelevant alternatives forces any unrestricted ranking aggregator to copy one fixed person's preferences.
- The Borda count can reverse the social ranking of A and B when voters change only their placement of C, even if no individual changes their A-versus-B preference.
- Ordinal comparisons reveal which option a person prefers but not the strength of that preference, so point totals derived from rankings should not be mistaken for measured human utilities.
- Possible responses to Arrow's impossibility include restricting preferences to structured domains such as single-peaked rankings, relinquishing IIA, eliciting richer utility information, or aggregating distributions with approaches such as maximal lotteries.
Chapters
- RLHF collects pairwise judgments from human labelers, fits a reward model, then uses that model in downstream training.
- For one fixed prompt, the candidates are possible language-model completions, and the reward model's scores induce a single ranking.
- The lecture asks what properties a rule should satisfy when it compresses different annotators' preferences into one ranking.
- Roth illustrates three preference types: A>B>C, B>C>A, and C>A>B.
- The labelers may each have coherent rankings while disagreeing about which completion is best.
- A reward model must still produce one ordering, so aggregation must resolve these differences.
- In the three-ranking example, two of three labelers prefer A to B, so majority prefers A>B.
- Two prefer B>C, while two prefer C>A, yielding the cycle A>B>C>A.
- Because a scalar reward sorts candidates into a transitive ranking, it cannot represent this cyclic set of pairwise majorities.
- Arrow's theorem originated in social choice and election theory, where selecting one winner may not require ranking every candidate.
- A reward model assigns scores across completions, thereby inducing a full ranking rather than merely selecting one winner.
- The cyclic-majority example motivates studying all aggregation rules, not only pairwise majority voting.
- The alternatives are a finite set of possible completions for one prompt, and each labeler has a strict, complete, transitive ordering.
- Roth denotes the set of rankings over alternatives by L(C); an input profile contains N such individual rankings.
- A social ranking rule maps that N-person profile to one complete, transitive aggregate ranking.
- Pareto unanimity requires the aggregate to rank A above B whenever every labeler ranks A above B.
- The rule has no constraint from this axiom when even one person disagrees about A and B.
- This requirement is weaker than majority rule, which already fails to produce a transitive ranking in the cycle example.
- Independence of irrelevant alternatives, or IIA, says the aggregate ordering of A and B depends only on each labeler's comparison of A with B.
- Changing how people rank a third option C must not change the collective ordering of A and B if nobody changes their A-versus-B judgment.
- IIA compares the outputs on two profiles with identical individual A-versus-B comparisons.
- A dictatorship is a rule that copies one fixed labeler's complete ranking for every possible input profile.
- It satisfies Pareto unanimity because the dictator is among the people who agree, and it satisfies IIA because only that person's pairwise comparison determines the output.
- The defect is that the other N−1 labelers have no influence, so the rule does not meaningfully aggregate their preferences.
- With M alternatives, the Borda count assigns M−1 points to first place, M−2 to second place, and zero to last place.
- It sums each candidate's points across all labelers and ranks candidates by their totals, breaking ties by an arbitrary rule.
- Equivalently, it ranks candidates by their chance of beating a uniformly sampled opponent according to a uniformly sampled labeler.
- In a four-voter, three-candidate example, the first profile gives A six Borda points, B four, and C two.
- When voters change only where they place C, while each person's A-versus-B preference stays fixed, the totals become A four, B six, and C two.
- The Borda count therefore reverses the aggregate ordering of A and B, violating IIA.
- Pairwise labels record whether A is preferred to B, not whether A is slightly or substantially better.
- Borda points are internal to the aggregation rule, not measured human utilities; identical ordinal rankings can correspond to different utility strengths.
- Restricting the allowed preferences can avoid the general impossibility: with single-peaked preferences along a line, pairwise majority yields a consistent ranking.
- For at least three alternatives, every rule mapping individual rankings to one aggregate ranking that satisfies Pareto unanimity and IIA is dictatorial.
- The theorem does not say that either axiom is morally mandatory; it says a non-dictatorial rule must give up at least one under unrestricted preferences.
- Three alternatives are necessary for IIA's comparison with a third, potentially irrelevant option to have substance.
- Suppose every labeler ranks B either first or last; the lemma says the aggregate must also put B either first or last.
- If the aggregate instead ranks A>B>C, change the rankings of A and C while preserving every person's comparisons involving B, so everyone ranks C>A.
- IIA preserves A>B and B>C, forcing A>C by transitivity, while Pareto requires C>A, a contradiction.
- Fix all rankings of alternatives other than B, then construct N+1 profiles in which the first k labelers rank B first and the rest rank B last.
- The extreme-position lemma keeps aggregate B at either the top or bottom; Pareto places it at the bottom at k=0 and top at k=N.
- At some adjacent pair of profiles, one labeler's switch moves aggregate B from last to first; call that pivotal labeler D.
- For any target profile where D prefers A to C, construct an auxiliary profile that matches the pivotal profiles on comparisons involving B.
- IIA transfers the aggregate comparisons A>B and B>C from the pivotal profiles to the auxiliary profile.
- Transitivity gives A>C there, and IIA transfers that comparison back to the target profile, so D controls every comparison not involving B.
- Choose a third alternative C and construct a profile preserving everyone's A-versus-B comparison while placing C between A and B in D's ranking.
- D's established control over comparisons not involving B gives aggregate A>C; unanimous C>B then gives aggregate C>B by Pareto.
- Transitivity yields aggregate A>B, and IIA carries that result back to the original profile, establishing D's control over all pairs.
- Restricting the preference domain, as with single-peaked rankings, can make coherent non-dictatorial aggregation possible.
- A designer can use a rule such as Borda while accepting that it violates IIA, or elicit richer information such as utility strength instead of only binary comparisons.
- Roth previews maximal lotteries as a way to work with distributions over alternatives rather than first reducing preferences to one total ranking.
Transcript excerpt
0:05 Um okay cool. So last class we kind of you know laid out the our ambition for you know the topics we want to cover. Um we're going to start today with the real basics like thinking about before we start thinking about how we can align AI models or collections of AI models preferences like I just want to start thinking about what are preferences and what are the very basics of aggregation. So um yeah we're going to learn about an old theorem today arrows impossibility theorem but the the motivation fits modern RHF pipeline pretty well I think
0:55 so um you know again this is just sort of a summary slide but standard reinforcement learning for human feedback pipeline what's going to happen is we're going to take a test kind of labels. I like this one from various human labelers who might very well have different preferences. We're going to try to learn a reward model that can predict those preferences that we're going to use downstream for further training. And so somehow we're trying to compress like a bunch of incomparable human that come from human preference data like a single training objective. Um, and so like what we're gonna think
1:46 about today, what arrows and possibility theorem is about is about like okay like first of all like if we're going to try to learn a single set of preferences that is supposed to be representative of many people like what are some very basic that we might want to be aggregate to satisfy and um and like unfortunately Ely what we're going to see like the the reason arrows theorem is called arrows of possibility theorem is that there's essentially no way to aggregate preferences even while satisfying these two very basic meaning there's one way
This is the start of the transcript. Save this video free for the whole transcript, searchable and time-coded.
Related notes
Summary, takeaways, and chapters were generated by AI from the video's transcript and may contain errors. The video belongs to its creator, Aaron Roth.