Mathematical Foundations of AI Alignment, Lecture 18 (Model Homogeneity From Competitive AI Markets)
 Watch on YouTube →
Overview
The lecture studies whether competitive AI markets should already absorb simple ensemble improvements, then derives what the absence of those improvements implies about model errors. For binary predictors, a no-arbitrage assumption for affordable threshold votes yields an error-union bound of 2α plus the models’ total excess error; a stronger assumption covering all affine weighted votes yields a shared hard core of mass at least 2α where every model performs at chance.
Key takeaways
- Five independent binary predictors with 10% error each reduce majority-vote error to about 0.856%, while perfectly correlated errors provide no voting gain.
- The efficient-market hypothesis for AI treats a cheap ensemble that improves cost and accuracy as a potential commercial arbitrage opportunity, not as a guaranteed market law.
- If every affordable threshold vote has error at least α, the union of model error sets is bounded by 2α plus the sum of each model’s excess error over α.
- A large excess-error term weakens the threshold-vote bound, so the result is most informative for models close to the best error available at their joint budget.
- If every affordable affine weighted vote fails to beat α, the models share a hard core of mass at least 2α on which each has exactly 50% accuracy.
- The hard-core proof uses LP strong duality to equate maximum hard-core mass with minimum hinge loss, then randomized score thresholds to relate hinge loss to 0 to 1 error.
Chapters
- The lecture asks whether commercially available models should provide the diversity that makes helpful ensembles possible.
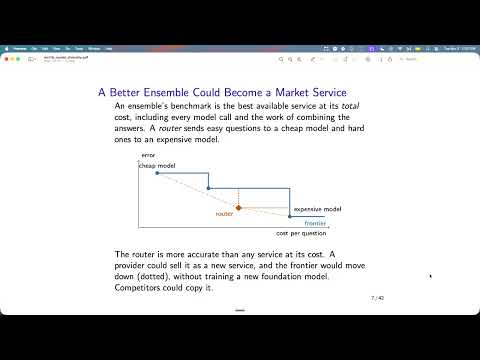
- A provider could combine models or route queries among them, then package a cheaper or more accurate service.
- The central question is what error patterns follow when simple combinations cannot improve on the available cost-accuracy frontier.
- Five binary predictors with independent 10% error rates can achieve about 0.856% error under majority vote.
- Majority vote is wrong only when at least three of the five models are wrong on the same question.
- If all five models make exactly the same errors, voting cannot improve accuracy, illustrating why error correlation matters.
- The relevant comparison places model cost on the horizontal axis and error on the vertical axis.
- A service improves on the frontier if it is both cheaper and less error-prone than existing options.
- Ensemble cost depends on the method: querying every model costs the sum of their prices, while routing can call only a selected model.
- The proposed hypothesis says mature competition should absorb inexpensive ensemble improvements into the services buyers can purchase.
- If a simple router or vote beats the existing frontier at the same budget, a provider could package it and profit from the improvement.
- The hypothesis is a motivating assumption, not a theorem that competition always makes markets efficient.
- At budgets far beyond the combined price of every model, a flat frontier makes the hypothesis implausibly strong if it rules out every possible improvement.
- Efficiency may differ across markets: coding and interior-design models can serve separate demand even when few buyers want a mixed benchmark.
- The results are most plausible at relevant budget levels where demand exists and providers have incentives to capture ensemble gains.
- Questions come from a finite population, each with a fixed true label in {−1, +1}; models are deterministic predictors.
- α(B) is the minimum error among models affordable at budget B.
- Including both constant predictors for free ensures the best binary error α is at most 1/2.
- For K jointly affordable models, threshold vote Vq predicts +1 when at least q models predict +1, and −1 otherwise.
- The thresholds range from permissive V1 to unanimous VK, with strict majority as an intermediate rule.
- Every threshold vote queries the full collection, so its cost is the sum of the individual model costs.
- The first formal assumption is that every affordable threshold vote has population error at least α(B).
- The theorem tracks U, the union of the questions on which any model errs, and each model’s excess error δj = err(hj) − α.
- This assumption expresses the efficient-market idea specifically for threshold voting, rather than proving that real markets satisfy it.
- For each question, the number of positive model responses equals the number of threshold votes that predict +1.
- Summed across questions, threshold votes preserve the total number of errors made by the original models.
- If no threshold vote beats α, the error-union bound is |U| ≤ 2α + Σj δj.
- When five models each have error α = 0.10 and zero excess error, the bound places all their errors within at most 20% of the benchmark.
- Large excess errors can make the bound nearly vacuous; a model far from the budget frontier contributes a larger δj.
- If measured error unions exceed the bound, the contrapositive indicates that some threshold vote must beat the frontier under the theorem’s setup.
- When models have equal error α and the union of their errors is at most 2α, each model fails on at least half of that union on average.
- Equivalently, questions in the union have at least K/2 failing models on average.
- Questions with identical model-response profiles are indistinguishable to a deterministic voting aggregator, even if their correct labels differ.
- A weighted vote assigns each model a real weight, allows negative weights, adds an intercept, and predicts from the sign of the resulting score.
- The stronger market assumption rules out frontier improvements by every affordable affine weighted vote, not only threshold rules.
- A hard core is a benchmark weighting where labels are balanced and every model is correct exactly half the time.
- The primal linear program maximizes hard-core weight subject to valid weights, balanced labels, and chance-level accuracy for every model.
- Strong duality identifies the maximum hard-core mass with the minimum hinge loss achievable by a weighted score.
- This identity turns the search for a large common hard core into an optimization problem over model scores.
- The proof shifts an optimal score by a threshold τ sampled uniformly from [−1, 1], then predicts from the shifted score’s sign.
- For each question, averaging over τ bounds the randomized classifier’s 0 to 1 error by half the score’s hinge loss.
- Some fixed threshold must therefore have error at most half the minimum hinge loss; the no-improvement assumption forces that hinge loss to be at least 2α.
- Under the stronger weighted-vote assumption, every jointly affordable model collection has a hard core of benchmark mass at least 2α.
- On that weighted region, every model is exactly 50% accurate; the result also implies an error-concentration bound.
- The practical conclusion is that adding models does not guarantee useful diversity when a mature market has already absorbed simple ensemble gains.
Transcript excerpt
0:00 I'm Sophia. Erin's in New York today. So, he's not gonna be here about project that Erin and I along with um some of our collaborators uh Mina Jagedan Ser and my friends have been working on. Um so last last class we were talking about like AI oversightes. Um and one of the morals that we kind of saw from uh that lecture was that um you know combining models can kind of help like if different viewers have uh complimentary objectives then they can kind of like help us steer the ensemble towards like not harmful outcomes. Um and we're going to kind of like take this moral and deliver like a little bit of bad news today. Um so the question
0:47 that we're going to be asking is like can we expect uh these sort of like helpful ensembles can we expect commercially available models to supply this kind of helpful diversity? Um so for instance uh like if I'm a potential model provider um and I see an opportunity for like arbitrage on a market. So say like I see the opportunity to ensemble together like three different models and um get like a better performing service. um then that might I might reasonably expect that I'm going to as like this potential provider I'm going to like package this combination um and sell the service um and make money. Um so the idea is that like you know competition can therefore sort of absorb these cheap improvements um into the menu of services that we
1:35 already have available on the markets. Um so this is kind of like a hypothesis about what happens in real markets. Um and then our question is going to be like when accurate models can't be improved by simple ensembles. So for
This is the start of the transcript. Save this video free for the whole transcript, searchable and time-coded.
Related notes
Summary, takeaways, and chapters were generated by AI from the video's transcript and may contain errors. The video belongs to its creator, Aaron Roth.