Lecture 5a
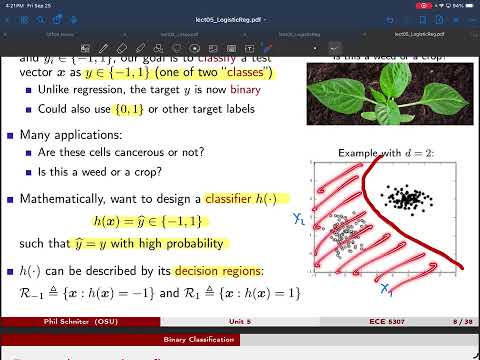 Watch on YouTube →
Overview
The lecture introduces binary linear classification through a University of Wisconsin breast cancer example, where tissue measurements are used to predict benign or malignant labels. It explains why least squares can produce poor classification boundaries, then derives binary logistic regression: a linear score z = b + wᵀx feeds a sigmoid probability model, whose parameters are fit by minimizing negative log-likelihood.
Key takeaways
- Binary classification predicts categories rather than ordered numeric values; a common encoding is −1 and 1, with the classifier restricted to those two outputs.
- A linear classifier uses z = b + wᵀx and assigns classes by the sign of z; its decision boundary is the hyperplane b + wᵀx = 0.
- Least squares can shift a classification boundary in response to a distant sample because it penalizes numeric residual size, even when that sample is already easy to classify.
- Logistic regression models P(y = 1 | z) = 1/(1 + e⁻ᶻ), giving probability 0.5 at z = 0 and increasingly confident predictions as the score moves away from zero.
- For a one-feature logistic model, the weight sign controls the direction of the probability curve, its magnitude controls sharpness, and the intercept shifts its midpoint to x = −b/w.
- With independent training samples, maximizing the logistic likelihood becomes minimizing a summed negative log-likelihood; the resulting parameter-fitting problem is convex.
Chapters
0:00
Breast Cancer Diagnosis Introduces Categorical Targets
- The University of Wisconsin example uses microscope-based tissue measurements, including cell size and shape uniformity, to classify samples as benign or malignant.
- Unlike regression targets, classification labels are categories without a meaningful larger-than relationship.
- The features are integer-quantized from 1 to 10, so repeated feature pairs are displayed with larger dots and colors for the two classes.
5:30
Binary Labels, Image Features, and Decision Regions
- Binary labels are commonly encoded as either −1 and 1 or 0 and 1, although the encoding can affect derivation details.
- An RGB image with 100 × 400 pixels becomes 120,000 numeric features, three color values per pixel.
- A classifier H maps each feature vector to one of two labels, dividing the input space into class-specific decision regions.
11:09
Linear Scores Create Hyperplane Decision Boundaries
- Binary linear classification first computes the score z = b + w₁x₁ + … + w_d x_d.
- Thresholding assigns label 1 when z ≥ 0 and label −1 when z < 0.
- The decision boundary is the set of inputs satisfying b + wᵀx = 0, a line for two features and a hyperplane in higher dimensions.
15:45
Affine Linearity and the Meaning of Linear Separability
- The score is affine-linear in the features because of the intercept b, but linear in the parameters b and w, which makes parameter fitting tractable.
- Without an intercept, a linear decision boundary must pass through the origin; b allows the hyperplane to shift away from it.
- A dataset is linearly separable when some hyperplane places every training sample on the correct side, and multiple valid boundaries may exist.
20:00
Feature Transformations Make Nonlinear Patterns Separable
- Many real datasets are not linearly separable in their raw features, and a linear boundary may leave training errors.
- Linear models remain useful for feature selection: after standardization, coefficient magnitudes can indicate which features are more predictive.
- Transforming features can expose a linear boundary; for circular data, adding a radius feature can separate inner and outer classes.
- Neural networks also use linear layers as components alongside more complex feature transformations.
25:50
Why Least Squares Can Misplace a Classification Boundary
- Least squares can be applied to numeric class labels by fitting a real-valued score and thresholding it, but its residual objective may not match classification accuracy.
- In a one-feature example, moving an easily classified positive sample farther away pulls the least-squares line and shifts its zero crossing, causing training mistakes.
- The Gaussian-noise model underlying least squares assumes targets cluster around a fitted line, unlike binary labels whose distances from that line do not behave as Gaussian residuals.
- The breast cancer scatter plot shows a similar issue: dispersed malignant samples can pull the least-squares boundary into a position that misclassifies benign samples.
34:00
Writing a Two-Feature Boundary as a Line
- For two features, the boundary equation b + w₁x₁ + w₂x₂ = 0 can be rearranged as x₂ = −b/w₂ − (w₁/w₂)x₁.
- In this line form, the intercept is −b/w₂ and the slope is −w₁/w₂, making the boundary straightforward to plot from fitted coefficients.
- The lecture returns to the two-stage classifier: calculate z from the features and coefficients, then threshold its sign.
37:00
The Sigmoid Converts Scores into Class Probabilities
- Binary logistic regression models P(y = 1 | z) as eᶻ/(1 + eᶻ), equivalently 1/(1 + e⁻ᶻ).
- At z = 0, the model assigns probability 0.5 to class 1; positive scores raise that probability toward 1, while negative scores lower it toward 0.
- Because the labels are 1 and −1, P(y = −1 | z) = 1/(1 + eᶻ), the complement of the class-1 probability.
46:10
Weights Control Sigmoid Direction, Sharpness, and Position
- With a single feature and zero intercept, z = wx: the sign of w determines whether the sigmoid increases or decreases with x.
- The magnitude of w controls transition steepness: smaller weights spread the probability change over a wider feature range, while larger weights make it sharper.
- A nonzero intercept shifts the transition center to x = −b/w, where the predicted class-1 probability is 0.5.
49:00
Maximum Likelihood Replaces Least Squares Fitting
- Maximum likelihood estimation first specifies a probability model for targets given features and parameters, then chooses parameters that maximize the training-data likelihood.
- Minimizing negative log-likelihood is equivalent and is often easier to optimize than maximizing likelihood directly.
- For linear regression, a Gaussian model yields a negative log-likelihood equivalent to residual sum of squares, recovering least squares.
- Logistic regression uses the sigmoid-based conditional class probabilities instead of the Gaussian additive-noise model.
52:00
Logistic Negative Log-Likelihood and Model Results
- Assuming independent training samples makes the likelihood a product of per-sample probabilities; taking the negative logarithm turns it into a sum.
- Switching indicators select the appropriate probability expression for each label, 1 or −1, yielding the logistic negative log-likelihood to minimize over b and w.
- The resulting optimization problem is convex and solvable with an algorithm, though the lecture defers optimization details to Unit 6.
- On the example data, logistic regression keeps the boundary in a sensible position despite a distant sample and gives class probability 0.5 at the boundary.
Summary, takeaways, and chapters were generated by AI from the video's transcript and may contain errors. The video belongs to its creator, Prof. Schniter.