10/19/26: Lect-08 (cont.)
Overview
Deeper CNNs are not automatically better: their value comes from composing filters and expanding receptive fields, while each generation of architecture addresses specific limits in training, parameter count, or kernel design. The lecture traces ImageNet-driven progress from AlexNet's 2012 breakthrough through VGG, Network in Network, and GoogLeNet, then explains weight decay, dropout, data augmentation, and batch normalization as tools for improving generalization and making deep networks trainable.
Key takeaways
- Stacking two 3×3 convolutions provides a 5×5 receptive field with 18C² parameters, fewer than the 25C² required by a single 5×5 convolution.
- AlexNet reduced ImageNet top-5 error from about 26% in 2011 to roughly 15.3% in 2012, combining a much larger CNN with ReLU and regularization methods.
- Dropout zeros selected hidden activations during training and scales retained activations by 1/(1−p); inference uses the full network without dropping units.
- Data augmentation improves training variety but does not create independent examples, and transformations such as rotation or flipping are useful only when they preserve the task's semantics.
- VGG's repeated 3×3 blocks achieved about 7.3% top-5 error but used roughly 138 million parameters; Network in Network instead used 1×1 convolutions and pooling to reduce classifier parameters.
- Batch normalization stabilizes deep networks by normalizing mini-batch activations, using per-channel statistics for convolutional tensors and running statistics at inference.
Chapters
- A 3×3 convolution uses shared weights across an image, unlike a fully connected layer with weights tied to input positions.
- Stacking convolutional layers composes filters, allowing later layers to build on features such as edges detected earlier.
- Two 3×3 layers cover a 5×5 receptive field with 18C² parameters, compared with 25C² for one 5×5 layer.
- The history of CNNs is a sequence of solutions to earlier limitations, not a simple rule that more layers are always better.
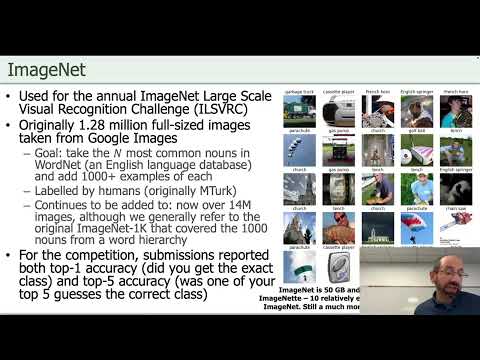
- The original ImageNet contained about 1.2 million images across 1,000 categories, including 90 dog breeds.
- ImageNet competitions created a shared target and incentives that helped accelerate computer vision research.
- ImageNette offered 10 easier-to-distinguish classes, while ImageWoof focused on the harder task of distinguishing dog breeds.
- Top-5 accuracy counts a prediction as correct when the true class appears among the five highest-scoring outputs.
- In 2011, leading ImageNet entries had about a 26% top-5 error rate; AlexNet cut the error to roughly 15.3% in 2012.
- AlexNet beat the second-place 2012 entry by more than 10 percentage points, a sharp departure from earlier incremental gains.
- The model scaled the LeNet approach from roughly 60,000 to 60 million parameters and used ReLU activations.
- AlexNet helped establish deep CNNs as a major turning point in image classification; human top-5 error on ImageNet was estimated at about 5%.
- AlexNet is commonly described as eight layers: five convolutional layers followed by three fully connected layers.
- A convolutional layer often groups a convolution, activation, and optional pooling operation, even though these are separate PyTorch calls.
- The example network takes three-channel RGB images resized or cropped to 224×224, then expands channel counts from 3 to 96, 256, 384, and 256.
- A first 11×11 convolution with stride 4 and padding 1 changes a 224-pixel input dimension to 54; published implementations differ slightly on input size and hyperparameters.
- Weight decay adds a penalty for large weights to the task loss, discouraging a model from fitting training data with unnecessarily complex parameters.
- The L2 form adds λ/2 times the squared weight norm; the one-half factor cancels the 2 produced by differentiation.
- Ridge regression uses an L2 penalty, while lasso regression uses an L1 penalty.
- For stochastic gradient descent, applying the penalty through the loss or equivalently through the gradient gives the same result, though some later optimizers treat the distinction differently.
- During training, dropout randomly sets selected activations to zero, reducing dependence on any single neuron.
- With dropout probability p, retained activations are scaled by 1/(1−p), preserving their expected value.
- Dropout injects noise into hidden activations and can make predictions more robust to small changes in inputs.
- At inference, the full network runs without randomly dropping activations.
- PyTorch transforms can randomly crop, flip, rotate, jitter, or mask training images, with augmentation applied during training rather than prediction.
- AlexNet described a space of 2,048 possible augmentations, but this did not turn 1.2 million images into two billion independent examples.
- Augmented versions of one image provide varied inputs, not new independent samples; the transformation must preserve the task's meaning.
- For a bearing-fault dataset, masking in the time or frequency domain may be meaningful, while image-style rotation may not be.
- The Oxford VGG models, including VGG16 and VGG19, organized networks as reusable blocks of repeated convolutional layers.
- VGG standardized on 3×3 kernels, using depth rather than a sequence of hand-picked large kernels to grow receptive fields.
- Three stacked 3×3 convolutions cover a 7×7 receptive field and can use fewer parameters than a single 7×7 convolution.
- VGG19 achieved about 7.3% top-5 error, but its roughly 138 million parameters and computation demands exceeded AlexNet's.
- Network in Network blocks insert 1×1 convolutions after spatial convolutions to mix channels and adjust their count.
- A 1×1 convolution acts like a channel-wise fully connected transformation shared across image locations, preserving spatial structure.
- Global average pooling can replace large fully connected classifier layers, reducing the architecture to roughly one million parameters in the discussed example.
- The approach can be much smaller than AlexNet or VGG, though deep networks may still encounter optimization problems.
- GoogLeNet, also known as an Inception model, achieved about 6.7% top-5 error in the 2014 ImageNet competition.
- An Inception block runs multiple paths in parallel, including 1×1 and 3×3 convolutional operations, then concatenates their output channels.
- Instead of choosing one kernel size in advance, the network learns which parallel features are useful through backpropagation.
- The architecture separates an input-processing stem, a repeated Inception body, and a classification head, while using fewer parameters than VGG19.
- Training ImageNet-scale models required substantial compute, storage, and planning, even when successful architectures made the process look straightforward.
- Experiments with Network in Network initially produced a nearly flat loss around 2.3, indicating little learning in a 10-class setup.
- Dead ReLU activations can accumulate when layer outputs drift in scale or become negatively shifted, cutting off gradients and halting learning.
- Adding batch normalization improved the demonstrated model's training, though the technique was developed after the original architecture.
- Batch normalization standardizes a layer's outputs using the mean and variance of the current mini-batch, helping keep activations and gradients in a workable range.
- For a normalized activation x̂, learned scale γ and shift β restore flexibility after normalization.
- For fully connected layers, normalization is typically applied after the affine transformation and before the activation function.
- For convolutional layers, normalization is computed separately for each channel; PyTorch provides BatchNorm1d and BatchNorm2d for the corresponding cases.
- During training, batch normalization computes statistics from the current batch; during inference, it uses running mean and variance accumulated across training batches.
- The learned γ and β values are updated by gradient descent, but the running mean and variance are tracked as statistics rather than learned parameters.
- A batch size of one cannot provide meaningful across-example statistics for the fully connected normalization example.
- Inference assumes the test data has a distribution broadly similar to the training data, so the stored statistics remain useful.
- A check for whether PyTorch gradients are enabled distinguishes training from inference in the example implementation.
- The implementation accepts rank-2 tensors for linear layers and rank-4 tensors for convolutional data shaped as batch, channels, width, and height.
- For convolutional inputs, it computes means and variances over dimensions 0, 2, and 3, preserving separate statistics for each channel.
- A momentum value controls how running statistics blend old and new batch estimates; these statistics are maintained separately for each layer.
Transcript excerpt
0:00 Uh let's go ahead and get started. We're we're in week nine of the semester and and we're finally at a point where we can start covering sort of [clears throat] deeper neural networks and specifically uh deeper CNN's deeper convolutional neural networks and we built up there slowly and things are going to kind of accelerate really starting uh today starting at this point in the semester. Um and and the question we really have to answer properly we left off here roughly on Wednesday last week is what does it mean? Why why is it why does it matter that one can start to build and train deeper networks? Really, the question is what does a deeper CNN actually get you? One potential takeaway is that well deeper is better. If I have more layers, it's clearly a better network. And there's all sorts of evidence that that's not necessarily the case. But there are some things that the depth itself, at least for CNN, does buy
0:48 you. One thing we saw back in the previous lecture where we introduced connets is that you know a single filter or a single kernel can get you detecting edges or blurring or sharpening and then you have a relatively small number of weights right versus the corresponding uh fully connected network fully connected layer where you have n cross n weights for my input resolution. I can have a relatively small kernel 3x3 5x5 11 by 11 and that gets shared across the entire image. As you stack those layers, as you go from one CNN layer to a second convolutional layer and so forth, you can start to apply filters upon filters, right? You have your first layer of filters that maybe grabs the edges. Then your second layer after that first layer
This is the start of the transcript. Save this video free for the whole transcript, searchable and time-coded.
In this course
Related notes
Summary, takeaways, and chapters were generated by AI from the video's transcript and may contain errors. The video belongs to its creator, Joseph Zambreno.