Transformer language models
Overview
Mohit Iyyer explains how causal self-attention scales into a Transformer through multi-head attention, stacked layers, positional strategies, and residual connections. He also shows how causal masks can expose position information, why every layer must remain masked to prevent future-token leakage, and how prefill builds a reusable key-value cache for autoregressive decoding.
Key takeaways
- Causal self-attention can compute all training positions in parallel using matrix operations, provided a mask blocks attention to future tokens.
- A causal mask can indirectly reveal position: with uniform attention, a token's hidden state can encode how many prefix tokens are visible through the weighted average of value vectors.
- Multi-head attention gives each head separate query, key, and value projections, allowing the model to learn multiple attention patterns before combining them into one token representation.
- Causal masking must be applied at every Transformer layer; otherwise, later-layer representations can leak future-token information and let the model cheat during training.
- Residual connections provide a shorter gradient path around complex attention blocks, helping optimization in deep Transformer networks.
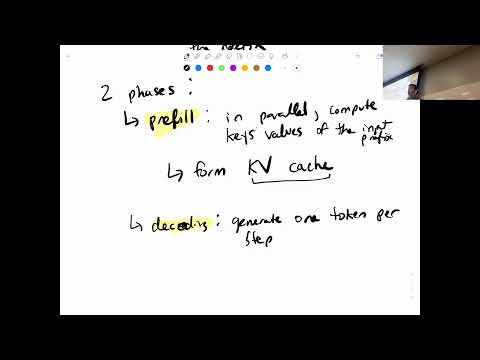
- Transformer inference uses a prefill phase to compute prompt keys and values, then reuses them in a KV cache while generating one token per decoding step.
Chapters
- Self-attention computes query-key dot products, applies a causal mask, then uses the resulting weights to combine value vectors.
- The query, key, and value matrices come from learned projections WQ, WK, and WV applied to the input embeddings or previous-layer representations.
- Matrix operations let a training pass compute hidden states for all sequence positions in parallel, while causal masking prevents access to future tokens.
- A learned position vector Pi can be added to token embedding Ci before the WQ, WK, and WV projections.
- An example model trained with 500 position embeddings cannot directly represent a 700-token sequence.
- Absolute embeddings assign separate representations to positions such as 36 and 500, although language tasks often depend more on relative distance.
- Rotary position embeddings, or RoPE, rotate query and key representations to introduce position-dependent attention scores rather than adding a learned vector to each token embedding.
- The lecture contrasts RoPE with no positional encoding, abbreviated as NoPE, which adds no explicit position information inside attention layers.
- NoPE can still exploit the causal mask, which gives each position access to a different number of preceding tokens.
- In a toy example with WQ set to zero, all unmasked attention scores are equal, so the post-softmax weights are uniform over the available prefix.
- At position three, attention assigns one-third weight to each of three visible tokens; at position two, it assigns one-half to each of two.
- Because each hidden state is a weighted average of value vectors, those weights can carry information about how many tokens have appeared.
- Explicit position encodings tell the model that sequence order matters instead of requiring it to infer order from causal-mask patterns.
- Iyyer describes position information as a useful inductive bias that can make learning easier, even if a sufficiently capable masked model can recover it from data.
- Adding learned position vectors may alter token representations, while RoPE introduces positional effects through query-key interactions instead.
- A single attention head uses one set of query, key, and value projections, limiting the attention pattern to one learned view of the prefix.
- Each additional head has its own WQ, WK, and WV matrices and can learn a different attention pattern.
- Possible head behaviors include attending to recent words, sentence subjects, nouns, named entities, or other syntactic and semantic properties.
- Each head independently applies masked attention and produces a hidden state for every token position.
- The per-head hidden states at the same position are concatenated, then passed through a feed-forward transformation with a nonlinearity such as ReLU.
- The feed-forward projection combines information from multiple heads and maps the concatenated representation back to the model's hidden dimensionality.
- A Transformer layer can take a sequence of vectors as input, whether those vectors are initial token embeddings or outputs from an earlier layer.
- Each layer repeats masked multi-head attention and a feed-forward projection, using new parameters rather than sharing attention matrices across layers.
- Model depth depends partly on available compute and training data: more data and compute can support more layers.
- After L Transformer layers, the top-layer vectors are the final token representations, also called hidden states.
- A softmax applied to the relevant final-layer representation produces a distribution for the next token, such as predicting “is” after “My favorite LLM.”
- The repeated attention and feed-forward blocks let deeper models represent more complex relationships between tokens.
- Every layer needs a causal mask because a later-layer representation can contain information gathered from other token positions in earlier layers.
- If a position can attend to a future token's representation at any layer, the model can leak the answer during training instead of learning to predict it.
- The feed-forward transformation combines heads at the same position, so it must receive representations whose attention computations have all respected the causal mask.
- Layer normalization re-centers and rescales vectors at each layer to help stabilize Transformer training.
- Scaled dot-product attention divides query-key scores by the square root of the vector dimension, limiting score magnitudes as dimensions grow.
- Residual connections add a layer's input to its output, giving gradients a shorter route through deep networks and helping optimization.
- At inference, a language model receives a user-provided prefix or prompt and generates a response one token at a time.
- Decoding can use strategies such as greedy selection or truncated sampling to choose each next token.
- Inference separates processing the existing prompt from generating new tokens, unlike training, which computes predictions across positions in parallel.
- During prefill, the model processes the entire input prefix in parallel and computes its key and value representations.
- The first generated token's query attends to the cached keys and values for the prompt; prompt queries are not needed again because the model is not predicting new tokens at those positions.
- The cache is extended with each generated token's keys and values, avoiding recomputation of earlier representations at every decoding step.
- A KV cache grows with sequence length because it retains keys and values for all previously processed tokens.
- Research on compressing or pruning the cache matters for serving systems such as OpenAI and Anthropic, where long contexts increase memory demands.
- The next topics are scaling, training data, and the distinction between pre-training and post-training.
Transcript excerpt
0:17 All right. So today we are going to be continuing where we left off from um last time where we tal talking about the attention mechanism um and moving forward to kind of incorporating that into a much larger scale model the transformer which features a couple of different things that extend what we were talking about last time. So we talked about the uh attention mechanism. Last time we actually talked about a single head attention mechanism and today we will expand that to uh multi-head self attention where each head can um learn to focus on a different property of the prefix. Um that's the high level intuition. We will also talk about
1:07 stacking multiple of these multi head self attention layers on top of each other before you reach the softmax. Um this allows you to express more complex relationships between the uh input prefix and the output especially as we um aim to scale up our model to potentially like trillions of uh training tokens. Um we want to scale up our model um in the same way so that it has more parameters. We talked about the parameters of the self attention um language model as having the WQ W K WV weight matrices for um the single head that we talked about. And now we'll see
1:58 that we can just multiply the number of parameters dramatically by adding more heads and adding more layers. Um so that's kind of where we're going today. Um there are also a couple of concepts um uh after we cover the um kind of multi head aspect that um I wanted to emphasize regarding what we do at test time when we're decoding from the model. Um there's uh as we talked about last time a difference in behavior right at
This is the start of the transcript. Save this video free for the whole transcript, searchable and time-coded.
In this course
Related notes
Summary, takeaways, and chapters were generated by AI from the video's transcript and may contain errors. The video belongs to its creator, Mohit Iyyer.