STAT 638 (Fall 2026), Lecture 10
 Watch on YouTube →
Overview
Samiran Sinha compares classical and Bayesian methods for assessing count-data models, using 40 observations and Poisson examples to show how simulation checks, chi-square goodness-of-fit tests, and posterior predictive checks can reveal model mismatch. He then explains Bayesian model selection with Bayes factors for testing a fixed Poisson mean of 2 against an unknown mean, and introduces the negative binomial distribution and the brms R package as tools for overdispersed counts.
Key takeaways
- A simulation-based goodness-of-fit check for Poisson(2) can use 10,000 replicated datasets of 40 observations and compare statistics such as the mean or zero count with the observed values.
- For the example’s five grouped count categories, the chi-square statistic is 5.44 and the fixed-parameter test has 4 degrees of freedom, producing p = 0.245.
- When λ is estimated from the data, the chi-square degrees of freedom must account for that fitted parameter: five categories yield 5 − 1 − 1 = 3 degrees of freedom.
- A Bayesian posterior predictive check must resample λ from its posterior for each replicate; fixing λ would fail to represent uncertainty about the unknown Poisson mean.
- Bayes factors compare integrated likelihoods, not just best-fitting parameter values: B₁₀ above 3 favors the alternative in Sinha’s rule of thumb, while values below 1/3 favor the null.
- The negative binomial variance μ + μ²/ω accommodates overdispersed counts and converges to the Poisson model as ω grows; brms can fit the model and provide marginal likelihoods for comparison.
Chapters
0:00
Model Selection Begins with 40 Poisson Counts
- Samiran Sinha frames the lecture around model selection, using 40 count observations as the working dataset.
- The first question is whether counts follow a Poisson distribution with fixed mean λ = 2 or a Poisson model with unknown λ.
- Sinha notes that the same model-checking ideas can extend to distributions such as Bernoulli and normal.
3:00
Simulating Poisson Data to Check a Fixed-Mean Model
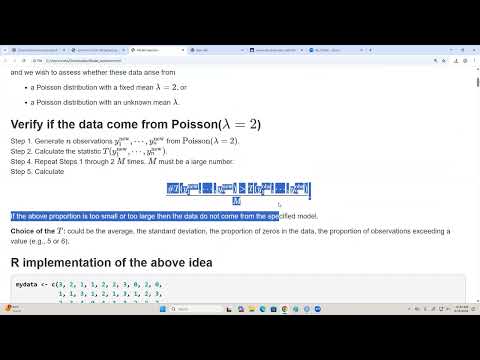
- Under the fixed-mean null model, generate many new datasets of size 40 from Poisson(2).
- For each replicate, calculate a statistic and compare it with the statistic from the observed counts.
- With 10,000 simulations, the fraction of replicates more extreme than the observed statistic indicates whether the data look unusual under Poisson(2).
7:00
Choosing Discrepancy Statistics and Interpreting Extremes
- Candidate statistics include the sample mean, standard deviation, number or proportion of zeros, and counts above a chosen threshold such as 6.
- The example’s simulation proportions include 0.12 for the mean comparison and 0.81 for the zero-count comparison; interpretation depends on which statistic is being assessed.
- Thresholds such as 0.05 and 0.95 are conventions, not universal rules; the choice should reflect the costs of false positives and false negatives.
11:00
Chi-Square Goodness of Fit for Poisson(2)
- The observed counts are grouped into five categories: 0, 1, 2, 3, and 4 or more.
- Expected frequencies are calculated by multiplying each Poisson(2) category probability by the sample size of 40.
- The Pearson statistic, summing (observed − expected)² / expected across categories, is 5.44; with 4 degrees of freedom its p-value is 0.245.
- Because 0.245 is not small under conventional thresholds, the test does not provide sufficient evidence against Poisson(2).
15:00
Pooling Sparse Categories and Checking Chi-Square Assumptions
- Sinha combines upper count values into a consecutive 4-or-more category because separate high-count cells would have small expected frequencies.
- The chi-square approximation relies on adequate expected counts; the lecture gives 5 as a practical minimum guideline.
- Pooling nonadjacent categories, such as combining 3 with 5 or more while excluding 4, would not be a sensible grouping.
17:00
Estimating λ Changes the Chi-Square Degrees of Freedom
- When testing the broader Poisson family, the maximum-likelihood estimate of λ is the sample mean, 2.25.
- Expected counts are recalculated using Poisson(2.25), and one estimated parameter must be subtracted from the degrees of freedom.
- For five categories, the corrected degrees of freedom are 5 − 1 − 1 = 3, giving a p-value of 0.2546.
- Using 4 degrees of freedom would give 0.3978; even when conclusions agree, the degrees-of-freedom adjustment is essential.
22:00
Bayesian Posterior Predictive Checks for Poisson Counts
- For independent Poisson observations, the likelihood is proportional to exp(−nλ)λ^S, where S is the sum of the counts.
- A Gamma prior with shape A and rate B is conjugate, producing a Gamma(A + S, B + n) posterior for λ.
- Posterior predictive checking repeatedly draws λ from that posterior, generates a replicated dataset of size n, and compares statistics such as the mean, standard deviation, or zero count.
- A predictive tail probability near 0.5 suggests compatibility; values near 0 or 1 flag a possible mismatch. In the example, the zero-count check equals 1.
29:00
Poisson Dispersion Checks and Alternative Count Models
- A Poisson distribution requires variance and mean to be equal, so a systematic variance-to-mean discrepancy can expose poor fit.
- If Poisson fit is inadequate, Sinha suggests alternatives including the negative binomial, zero-inflated Poisson, and Conway–Maxwell–Poisson models.
- The negative binomial handles overdispersion, while the Conway–Maxwell–Poisson model can accommodate both overdispersion and underdispersion.
33:30
Bayes Factors Compare λ = 2 with an Unknown Poisson Mean
- The hypothesis test assumes Poisson sampling and compares H₀: λ = 2 with H₁: λ unknown under a prior distribution.
- The null marginal likelihood is the likelihood evaluated at λ = 2; the alternative marginal likelihood integrates the likelihood against the prior over λ > 0.
- The Bayes factor B₁₀ is the alternative marginal likelihood divided by the null marginal likelihood, so constants cannot be dropped.
- Sinha presents B₁₀ > 3 as evidence favoring the alternative and B₁₀ < 1/3 as evidence favoring the null; values between these cutoffs are less decisive.
40:00
Continuous Priors, Point Nulls, and Negative Binomial Modeling
- Although λ = 2 lies within a Gamma prior’s support under H₁, a continuous prior assigns probability zero to the exact point λ = 2; some approaches exclude a small neighborhood around the null value.
- For a negative binomial model with mean μ and shape ω, the variance is μ + μ²/ω, allowing variance greater than the mean.
- As ω approaches infinity, the extra variance term vanishes and the negative binomial approaches the Poisson model.
- Sinha demonstrates fitting with the brms R package, which provides default priors and supports custom priors; its marginal likelihood can be compared with the Poisson model’s for selection.
Summary, takeaways, and chapters were generated by AI from the video's transcript and may contain errors. The video belongs to its creator, Samiran Sinha.