[HD] EECS4302 F26 - 2026-09-29 (Tuesday) - Lecture 6
 Watch on YouTube →
Overview
Jackie Wang develops the foundations of formal-language theory needed for Assignment 1: systematic enumeration of strings, distinctions among alphabets, strings, languages, and membership problems, and regular-expression operators. The lecture then introduces DFA and NFA modeling through alternating binary strings, equal-count constraints, dead states, nondeterministic suffix detection, and the equivalence of regular expressions, DFAs, and NFAs.
Key takeaways
- A language over Σ is a subset of Σ*, while Σ* contains every finite string over Σ, including ε; the empty language ∅ and the singleton language {ε} are therefore fundamentally different.
- The implication Σ₁ ⊆ Σ₂ ⇒ Σ₁* ⊆ Σ₂* follows because every string formed from symbols in Σ₁ can also be formed when the larger alphabet Σ₂ is available.
- Regular-expression precedence is Kleene star, then concatenation, then union with +; confusing 10* with (10)* changes the accepted language, as shown by witnesses such as ε and 100.
- A DFA over {0, 1} must provide exactly one 0-transition and one 1-transition from every state, whereas an NFA may omit transitions or provide multiple transitions for the same symbol.
- Dead states encode irreversible violations: once consecutive equal symbols break the alternating-string condition, no future input can produce an accepted string.
- NFAs simplify patterns such as binary strings ending in 01 by nondeterministically guessing the start of the suffix, and subset construction converts that NFA into an equivalent DFA.
Chapters
0:00
Assignment 1 Preparation and Systematic String Enumeration
- Jackie Wang prioritizes the minimum formalism needed for Assignment 1 and postpones heavier mathematical notation until after the deadline.
- For an alphabet such as {A, B, C}, strings in Σ^4 can be enumerated with a four-level tree, where each root-to-leaf path produces one length-four string.
- The tree method prevents omissions by selecting every alphabet symbol independently at each of the four character positions.
- The same enumeration strategy can handle restricted-string exercises by pruning branches that violate the restriction.
5:00
Distinguishing an Alphabet from the Language Σ¹
- Σ denotes the alphabet itself, such as {0, 1} or {A, B, C}, whereas Σ¹ denotes the set of all strings of length exactly one over Σ.
- Σ¹ is a set of singleton strings, not a collection containing Σ¹, Σ², and other powers; that broader collection is associated with Σ+ or Σ*.
- The notation difference is categorical: alphabet symbols and strings are different mathematical objects even when they look similar.
- Jackie Wang reinforces that Σ⁰ contains the empty string ε, regardless of which finite alphabet Σ is used.
10:00
Interpreting the Implication Σ₁ ⊆ Σ₂ ⇒ Σ₁* ⊆ Σ₂*
- If every character in alphabet Σ₁ also appears in Σ₂, then every finite string constructible from Σ₁ is constructible from Σ₂.
- The Kleene star includes strings of lengths zero, one, two, and so on, so Σ* contains ε as well as all nonempty strings over Σ.
- The example {0, 1} ⊆ {0, 1, 2} illustrates why the second starred language can contain at least all strings from the first.
- A proof can be developed by showing that each string in Σ₁* uses only symbols that are also available in Σ₂*.
15:00
Languages as Subsets of Σ*
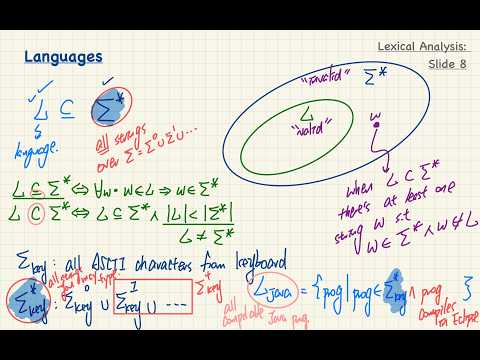
- A language L over alphabet Σ is a set of strings satisfying L ⊆ Σ*.
- For every string w, w ∈ L implies w ∈ Σ*; the language selects valid strings from the universe of all strings over Σ.
- A proper subset L ⊂ Σ* excludes equality with Σ*, meaning at least one string over Σ is not included in L.
- The distinction supports practical validation tasks, where valid programs or commands are separated from syntactically possible but invalid strings.
20:00
Keyboard Strings and the Language of Compilable Java Programs
- If Σ_keyboard contains all ASCII keyboard characters, then Σ_keyboard* represents every finite string that can be typed, including ε.
- The Java language L_Java is modeled as the subset of keyboard strings that form compilable Java programs.
- A misspelled keyword or an invalid operation such as multiplying an integer by an incompatible string can place an input outside L_Java.
- Set-comprehension notation expresses L_Java by restricting keyboard-generated strings according to whether Eclipse can compile them.
25:00
Empty Language versus the Language {ε}
- The language containing only ε is nonempty: L₁ = {ε} accepts exactly one string, whose length is zero.
- The empty language L₂ = ∅ contains no strings and rejects every input.
- ε is not the same as the empty language: ε is an element, while ∅ is a set with no elements.
- Jackie Wang recommends revisiting these two languages later with regular expressions, DFAs, NFAs, and ε-NFAs.
30:00
Computational Problems as Language-Membership Questions
- A computational problem can be formulated as deciding whether an input string w belongs to a language L ⊆ Σ*.
- For compilation, w may be a keyboard-generated string representing a valid Java program, while w′ may be a keyboard string that fails Java compilation.
- A string outside Σ* is not merely an invalid member of L; it is not a valid string over the selected alphabet at all.
- The membership perspective unifies recognition tasks such as compilation, pattern matching, and later automata execution.
35:00
Regular Expressions and Their Three Core Operators
- Regular expressions provide a textual way to specify regular languages, complementing diagrammatic DFA and NFA representations.
- The three central operators are Kleene star for zero-or-more repetition, concatenation for sequencing patterns, and plus for union or alternative choices.
- Regular expressions, DFAs, NFAs, and ε-NFAs are equally expressive for regular languages, so equivalent representations can be converted between one another.
- Jackie Wang connects regular expressions to ANTLR4 grammar files, where textual patterns are used as parser or lexer inputs.
40:00
Constructing a Regular Expression for Alternating 0s and 1s
- The target language contains binary strings with no consecutive equal symbols, so ε, 0, 1, 01, 10, and 0101 are valid examples.
- A first construction enumerates four pattern families: repetitions beginning with 01, repetitions beginning with 10, and versions prefixed by a single 1 or 0.
- The Kleene star correctly includes ε, allowing zero repetitions of a base pattern such as 01 or 10.
- The construction works by covering all possible starting symbols and alternating continuations, with harmless overlap between pattern families.
45:00
Factoring Regular Expressions and Applying Operator Precedence
- A second regular-expression construction factors repeated subexpressions, analogous to extracting helper methods from duplicated Java code.
- Regular-expression precedence is star first, concatenation second, and union using + last.
- Parentheses override the default precedence and can change whether repetition applies to one symbol or to an entire concatenated block.
- The examples contrast expressions equivalent to 1(0*) with (10)*, which recognize different sets of binary strings.
50:00
Witness Strings for Proving Regular-Expression Inequivalence
- To show two regular expressions are not equivalent, it is sufficient to find one witness string accepted by one expression but rejected by the other.
- For expressions corresponding to 10* and (10)*, ε distinguishes them because the starred grouped expression can accept zero repetitions while 10* still requires an initial 1.
- The string 100 is another witness for the difference between one initial 1 followed by any number of 0s and repetitions of the complete block 10.
- Membership statements should refer to the language denoted by a regular expression, since a string is an element of a language rather than an expression itself.
55:00
DFA Requirements and the Equal-Count Alternation Language
- A deterministic finite automaton has exactly one transition for every state and every symbol in the alphabet; for Σ = {0, 1}, each state needs one 0-transition and one 1-transition.
- The example language excludes ε and requires alternating 0s and 1s with equal numbers of both symbols.
- State meanings are defined by the input read so far, such as having read more 0s than 1s or having already violated alternation.
- An accepting state must satisfy all three conditions: nonempty input, equal counts, and alternating symbols.
1:00:00
DFA State Construction with Accepting and Dead States
- After reading 0 from the start state, the automaton enters a state representing more 0s than 1s while alternation remains valid.
- Reading another 0 from that state creates consecutive 0s, so the machine enters a dead state where the alternation condition can never be restored.
- Reading 1 after an initial 0 produces the balanced alternating string 01, reaching an accepting state.
- From the accepting state, reading 0 returns to the more-zeros state, while reading 1 enters the dead state because consecutive 1s violate alternation.
1:05:00
NFA Modeling of Strings Ending in 01
- The target language consists of binary strings whose final two symbols are 01, with any binary prefix, including the empty prefix.
- An NFA can use nondeterminism to guess when the arbitrary prefix ends and the final 01 suffix begins.
- One interpretation continues consuming arbitrary 0s and 1s as part of the prefix, while another interpretation begins matching the final 0 followed by 1.
- The resulting NFA is easier to design than a DFA for this pattern, but subset construction can convert it into an equivalent DFA; this conversion is relevant to Assignment 1.
1:09:00
Next Lecture, Assignment 2, and Project Preparation
- The next class will cover NFAs, ε-NFAs, and additional DFA/NFA conversions, including how strings are processed by each machine.
- Jackie Wang plans to show a short illustrative movie clip on Thursday while continuing the automata discussion.
- Project materials and Assignment 2 are expected before the reading week, with a brief Thursday briefing on the demanding requirements.
- Students are encouraged to use the lecture digest, templates, office-hour appointments, and Assignment 1 exercises for preparation.
Summary, takeaways, and chapters were generated by AI from the video's transcript and may contain errors. The video belongs to its creator, Jackie Wang.