[HD] EECS4302 F26 - 2026-09-24 (Thursday) - Lecture 5
 Watch on YouTube →
Overview
Jackie Wang introduces Assignment 1 for EECS 4302 and begins a formal treatment of lexical analysis. The assignment, worth 2% and due in two weeks, uses Java in Eclipse to implement regular-expression-to-ε-NFA and ε-NFA-to-DFA transformations; the lecture then defines alphabets, strings, and related set notation needed to understand finite automata and scanners.
Key takeaways
- Assignment 1 asks students to implement two language-preserving transformations: regular expression to ε-NFA, and ε-NFA to equivalent DFA.
- The assignment’s Java workflow uses Eclipse, console-based `toString` output, expected-output examples, and a web visualization tool rather than JUnit.
- Lexical analysis either passes a complete sequence of valid tokens to the parser or stops at the first invalid token with a lexical error.
- A finite, nonempty alphabet Σ generates `|Σ|^k` strings of length `k`; for example, lowercase English letters produce 26⁵ five-character strings.
- Σ+ excludes the empty string, while Σ* includes ε and therefore contains strings of every length greater than or equal to zero.
- Universal statements can be disproved with one counterexample, whereas existential statements require just one valid witness.
Chapters
0:00
Course Schedule, ANTLR 4 Preparation, and Assignment 1
- Jackie Wang notes that two weeks remain before reading week and plans to finish the current material beforehand.
- The ANTLR 4 tutorial series is emphasized as a central learning and assessment resource.
- Lexical-analysis and math-review slides are available; students are encouraged to study DFA, NFA, ε-NFA, and regular expressions ahead of class.
- Assignment 1 is a chance to earn credit with a best attempt while still reviewing its learning outcomes and solution after submission.
3:00
Importing the Assignment Starter Project into Eclipse
- Download the Assignment 1 starter project ZIP from eClass and launch Eclipse using a workspace folder you can locate later.
- Use File → Import → General → Existing Projects into Workspace, then select the archive-file option and browse to the ZIP.
- The starter project is intended for Eclipse, not IntelliJ; familiarity with Eclipse will also help with a later programming test.
- Keep track of the project folder because the full folder is part of the submission.
6:30
Assignment 1 Requirements: Regular Expressions and ε-NFAs
- Assignment 1 is worth 2% of the course grade and is due in two weeks.
- Implement a transformation from regular expressions to ε-NFAs and another from ε-NFAs to equivalent DFAs.
- The lexical-analysis and math-review lecture slides provide the required background; no separate ECS 2001 textbook reading is required.
- A private GitHub repository is acceptable during the semester; Wang says it can be made public after the course.
11:00
Testing Automata with Console Output and a Visualization Tool
- Assignment test classes construct automata using Java collections, then rely on methods such as `toString` to print concrete syntax.
- Copy the console output into the linked web tool to visualize an automaton; the tool visualizes syntax but does not perform the transformation.
- Compare generated output against the provided expected-output examples and use the test cases to check both input and output formats.
- The assignment does not use JUnit automation: output is printed to the console and checked manually in the web tool.
15:00
Assignment 1 as a Compiler-Style Intermediate-Representation Transformation
- The assignment models a small compiler pipeline: concrete syntax is parsed into a Java ε-NFA representation, transformed, then printed as concrete DFA syntax.
- The ε-NFA and DFA are distinct intermediate representations for different automata domains.
- The output DFA must be equivalent to the input ε-NFA; an arbitrary DFA is not a valid transformation result.
- Students may add methods or attributes, but should preserve the supplied classes’ inheritance and decoration and generally should not add new classes.
22:54
Math Review: Logic, Quantifiers, Sets, and Relations
- The math-review slides cover propositional operators such as implication, disjunction, and conjunction.
- Predicate logic introduces universal quantification (`for all`) and existential quantification (`there exists`), notation used in later formal definitions.
- Reviewing sets and relations supports precise definitions of DFA and NFA.
- Wang notes that the math-review material is part of the course and can also appear on the exam.
25:01
Lexical Analysis Scans Source Characters into Tokens
- Lexical analysis scans a program file character by character and checks words against token patterns specified with regular expressions or DFAs.
- If all words match valid token patterns, the scanner passes a sequence of tokens to the parser.
- If even one word fails to match, scanning reports a lexical error and stops before parsing.
- A misspelled keyword such as `CLA SS` illustrates an error caught at the lexical-analysis stage.
28:13
Automata Roadmap: Regex, NFA Conversion, and DFA Minimization
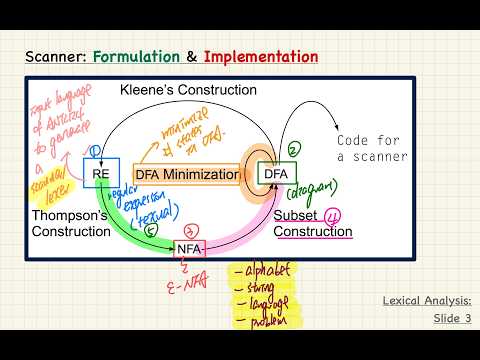
- The formal vocabulary develops in order from alphabet to string, language, and problem.
- Regular expressions provide textual language descriptions; DFA and NFA provide automata-based descriptions, with NFA transitions allowing multiple possible destinations for an input symbol.
- The subset-construction method converts an NFA to a DFA, while a separate construction converts regular expressions to ε-NFAs.
- A DFA can be minimized to an equivalent machine with fewer states; ANTLR 4 and similar generators automate much of this pipeline.
35:34
Alphabets and Set Comprehension Notation
- An alphabet is a finite, nonempty set of symbols; the binary alphabet has cardinality 2, while uppercase and lowercase English letters together have cardinality 52.
- Set enumeration explicitly lists members, whereas set comprehension uses a constraint after a vertical bar to describe which values to consider.
- The decimal-digit set can be specified by integers `D` satisfying `0 ≤ D ≤ 9`; restricting `D` to integers makes the definition precise.
- For integer pairs with `1 ≤ X ≤ 3` and `2 ≤ Y ≤ 4`, there are 3 × 3 = 9 possible members.
45:05
Strings, the Empty String, and Type-Correct Membership
- A string is a finite sequence of symbols drawn from an alphabet; the empty string ε has length 0.
- The sequence `01010` is a string over the binary alphabet, but it is not itself a member of the alphabet `{0, 1}`.
- Membership applies to individual symbols in an alphabet, while a multi-symbol string is formed by concatenation.
- Vertical bars can denote a set’s cardinality or a string’s length, depending on what appears between them.
49:49
Identity Elements for Concatenation and Familiar Operations
- The empty string ε is the identity for string concatenation because placing it before or after a string leaves that string unchanged.
- Zero is the identity for addition, and one is the identity for multiplication.
- True is the identity for logical conjunction, while false is the identity for logical disjunction.
- An identity must preserve the value on either side of the operation; matrix multiplication was raised as a noncommutative case with its own identity matrix.
54:00
Universal and Existential Quantifiers with Witnesses
- A universal claim requires a property to hold for every value satisfying its constraint; one counterexample disproves it.
- The claim that every positive integer `x` is greater than 10 is false because `x = 2` is a counterexample.
- An existential claim needs only one witness: there exists an `x` greater than 0 and 10 is true with witness `x = 11`.
- Universal definitions commonly combine constraints with implication, while existential definitions use conjunction to require both conditions.
58:06
Formal Definitions of Σ^k, Σ+, and Σ*
- For an alphabet Σ, strings of length `k` can be described as words `w` over Σ satisfying `|w| = k`.
- A length-`k` word has character positions from 0 through `k − 1`; each position must contain a member of Σ.
- Σ+ is the set of all nonempty strings over Σ, equivalent to the union of strings of lengths 1, 2, 3, and onward.
- Σ* contains strings of every length `k ≥ 0`, including ε; ε must be treated as a string, not as a set member without the appropriate set notation.
1:05:26
Counting and Enumerating Fixed-Length Strings
- The set of lowercase English strings of length 5 has cardinality 26⁵ because each of the five positions has 26 choices.
- For the alphabet `{A, B, C}`, there are 3⁴ strings of length 4.
- In general, an alphabet of cardinality `n` yields `n^k` strings of length `k`.
- The next class will continue with systematic enumeration of fixed-length strings.
Summary, takeaways, and chapters were generated by AI from the video's transcript and may contain errors. The video belongs to its creator, Jackie Wang.